













Matrix algebra provides a compact way to represent neural networks as matrix equations, where inputs are multiplied by weight matrices and biases are added; this approach enables efficient computation of linear transformations and is fundamental to understanding neural network frameworks like PyTorch and the attention mechanism used in transformers.
Matrix Algebra for Neural Networks Clearly Explained in Mathematics
Added:Basic Linear Algebra Concepts: Familiarity with vectors, basic matrix representation, and the concept of dimensions (rows and columns).
Fundamental Neural Network Structure: A conceptual understanding of what artificial neural networks are, including inputs, weights, biases, and outputs.
Introductory Python Programming: Understanding basic programming syntax, ideally with some exposure to numeric libraries like NumPy.
High-School Level Algebra: Comfort with algebraic variables, systems of linear equations, and function notation.
Backpropagation and Matrix Calculus: Learning how gradients flow through matrix operations, including Jacobian matrices and the chain rule in matrix form.
Deep Dive into PyTorch Tensors: Mastering tensor manipulation, tensor broadcasting, and resolving dimension/shape mismatch errors in deep learning frameworks.
Mathematical Mechanics of Attention Mechanisms: Studying the math behind self-attention, query-key-value (QKV) projections, and transformer architectures.
Optimization Algorithms: Understanding how gradient descent variants (like Adam or SGD) update weight matrices during network training.
78.3K views2.2Klikes30:00Original Release: 2023-12-11
If you can add and multiply, then you can do matrix stuff! Hooray! StatQuest. Hello, I'm Josh Starmer and welcome to StatQuest. Today we're going to talk about essential matrix algebra for neural networks and it's going to be clearly explained. Start small but then build as big as you want.
Lightning! Bam! This StatQuest is also brought to you by the letters 'A', 'B', and 'C'. 'A' always, 'B' be, 'C', curious. Always be curious. Not that you need to, but if you watched any of the StatQuest of videos on neural networks, then you already know that even the most state-of-the-art models, like transformers, can be explained with relatively simple diagrams and flowcharts. However, if you try to code neural networks using any of the tools that make the job easier, like PyTorch and PyTorch Lightning, then it won't be long before you need to look at the documentation and you'll see something like this.
Ugh!
Or you'll have a small bug in your code and you'll see an error like this.
Double ugh!
Or you might just want to read up on the latest trends and neural networks and not wait for StatQuest to explain it, and you'll see stuff like this.
Triple ugh! All this math looks complicated and hard to understand.
Don't worry, 'Squatch. We're going to learn how to read all of this gobbledygook one step at a time.
Bam!
All of these things are based on matrix equations, which provide a very compact way to describe neural networks. So if you want to understand the documentation, debug your code, or just read the latest manuscripts about neural networks, you need to know how to work with matrix equations.
So in order to understand how matrix equations apply to neural networks, we're going to show how this specific neural network translates into this compact matrix equation.
Ugh, that equation looks weird. Are you sure I'm going to understand it?
Don't worry 'Squatch. We will go through it one step at a time.
Okay.
However, we'll start by learning some basic terminology and build up an understanding of the strangest part of matrix equations, matrix multiplication.
And in order to do that, imagine StatSquatch just got a ticket to see Taylor Swift at the Friends Arena in Stockholm, Sweden. 'Squatch, are you ready for it?
Yes.
Where is your seat?
My seat is close to the front on stage left.
Now, if we put an x and y axis centered on the stage, then in terms of those axes, the coordinates for 'Squatch's seat are 2, 1. Now, for reasons that we will never, ever, ever understand, Taylor decides to flip the direction of her stage 180 degrees.
I knew she was trouble.
Anyway, rotating the stage means 'Squatch's seat and everyone else's needs to rotate as well. To determine the new x and y coordinates of 'Squatch's seat, we can use these equations. For example, if we plug in the original coordinates, x = 2 and y = 1, then the new x and y coordinates are -2, -1. In other words, these two equations transform the point 2, 1 into the point -2, -1. Oh no! It's the dreaded terminology alert. Because these equations, which transform the original x and y coordinates into new x and y coordinates, only multiply and add stuff to the original x and y coordinates, this transformation is called a linear transformation. For example, if we focus on the first equation and plug in x = 2 and y = 1, then we get -2. If we then increase x to 3, then we get -3. Likewise, increasing x to 4 gives us -4.
Thus, each time we increase the value for x by 1, we decrease the output by -1. In other words, a constant change in the value for x results in a constant change in the output. Because the amount of change in the output is always the same, just like the slope, or the amount of change in the y axis, of a straight line is always the same, this transformation is called a linear transformation. In contrast, if the transformation was 2 to the x, then plugging in x = 2 would give us 4. Plugging in x = 3 would give us 8. And plugging in x = 4 would give us 16. And we see that each time we increase the value for x by 1, the output increases by a different amount.
Because the amount of change in the output changes. Just like the slope of a curve changes, this transformation is called a nonlinear transformation. Anyway, going back to our original linear transformations, the reason I'm making big deal about linear versus nonlinear transformations is that matrix algebra is especially useful for linear transformations. Thus, using matrix notation, we can write out our linear transformation like this. In this example, we've put the old x and y coordinates into something called a row matrix or row vector. We can also call this row matrix a 1 by 2 matrix because it has one row and two numbers in that row. So we say it has two columns. We can also say that this matrix is one-dimensional because everything is on a single row. The coefficients, the numbers we multiply x and y by and define the transformation, go into a matrix. And we can call this a 2 by 2 matrix because it has two rows and two columns. Or we can call this a two dimensional matrix because it has multiple rows and columns. The coefficients in the first equation go into the first column in the matrix and the coefficients in the second equation go into the second column in the matrix.
Josh, this seems really weird and I have no idea how I will remember this.
Don't worry 'Squatch. We will explain exactly why we're doing all this in just a second.
And knowing why we do this will help you derive it on your own.
Bam!
Anyway, if, just like before, we let x = 2 and y = 1, then we can multiply the row matrix that contains the original coordinates by the transformation matrix with the coefficients.
Hey Josh, I know how to multiply numbers, but how do I multiply matrices?
We start by multiplying the row of x and y coordinates by the numbers in the first column in the transformation matrix. So, in this case, we start by multiplying 2 by -1, then we multiply 1 by 0. And lastly, we add the terms together. And this gives us the original transformation for the new x coordinate that we started with, which tells us that the new x coordinate is -2. Then we multiply the same row of x and y coordinates by the numbers in the second column in the transformation matrix. So that means we multiply 2 by 0 and 1 by -1. And lastly, add the products together.
And that gives us the original transformation for the new y coordinate that we started with, which tells us that the new y coordinate is -1. Combined, the matrix multiplication transforms the old x and y coordinates to the new x and y coordinates.
Bam? It seems like a lot of trouble to do the same thing as before.
Well, what if Taylor rotated the stage 90 degrees clockwise from where it was before?
Oops, she did it again?
No 'Squatch, that's Britney Spears. Anyway, where should 'Squatch sit? To determine the newest x and y coordinates for 'Squatch's seat, we can plug the coordinates we just calculated into these equations. And just like before, we can convert them into matrix notation by putting the x and y coordinates we just calculated in a one-dimensional row matrix with one row and two columns, and putting the coefficients into a two dimensional transformation matrix with 2 rows and 2 columns. The coefficients in the first equation go into the first column in the transformation matrix, and the coefficients in the second equation go into the second column in the transformation matrix. Now we plug in the x and y coordinates we calculated earlier, -2 and -1, and do the matrix multiplication just like before, row by column. We start by multiplying the row of x and y coordinates by the numbers in the first column in the transformation matrix. So we multiply -2 by 0, and we multiply -1 by 1, and then we add the terms together. And that gives us the newest x coordinate, -1. Then we multiply the same row of x and y coordinates by the numbers in the second column in the transformation matrix. So we multiply -2 by -1 and multiply -1 by 0, and then add the terms together.
That gives us the newest y coordinate 2. Thus, 'Squatch moves from -2, -1 to -1, 2.
Josh, I still don't get why we multiply matrices in such a strange way.
Well, the reason why we multiply the numbers in a row by the numbers in a column and then add the products together, is that when we use matrix multiplication to multiply the first transformation by the second transformation, which means we multiply the first row by the first column and add the products, and we multiply the first row by the second column and add the products, and then we multiply the second row by the first column and add the products. Note, because we are now using this second row of the first matrix, we put the result in the second row in the output. In other words, when we use a new row to do multiplication, we start a new row in the output matrix. Anyway, then we multiply the second row by the second column and add the products. And we end up with a new two-by-two transformation that combines the effects of both transformations. The new combined transformation transforms the original point directly to the newest point without having to take the intermediate steps.
In other words, matrix multiplication is funky so that we can easily combine a sequence of transformations into a single transformation. To convince ourselves that we can use the combined transformation to transform the original point to the newest point without having to do the intermediate steps. Let's multiply the original coordinates by the combined transformation. So we start by plugging in the original coordinates 2 and 1. Then we just do the row by column math. Beep boop boop boop boop beep boop boop boop boop, beep boop boop!
And we see that the combined transformation transforms the original coordinates, 2, 1, to the newest coordinates, -1, 2.
Bam!
Note, matrix multiplication is such that no matter how many times Taylor Swift changes her mind about which direction the stage should face, we can just multiply the individual transformations together to get a combined transformation. And that combined transformation allows us to go directly from the original location to the final location without having to do the intermediate steps. Bam. Okay, now that we understand why matrix multiplication is so funky, let's talk about another confusing thing about matrix multiplication. Because matrix multiplication is applied row by column, we can't just reverse the order of the matrices and expect things to work out the same. In fact, we can't even multiply these two matrices together because each row in the first matrix has two numbers and each column in the second matrix only has one number.
For example, if we try to multiply the first row of numbers in the first matrix by the first column of numbers in the second matrix, then we can multiply 0 by 2, but there is nothing to multiply this 1 by. In contrast, it's possible to multiply these two matrices because we have the same number of values in this row that we have in these columns. In general, the number of columns in the first matrix has to match the number of rows in the second matrix. If, for some reason, we want to switch the order of these matrices, then we need to change each row into a corresponding column.
Now we can do the multiplication correctly, row by column. Beep, beep, boop, beep, boop, beep, boop, boop. And after turning each row into a corresponding column, the math works out just like it did before. Note, because we turned the rows in the original matrices into columns, the output is now a column instead of a row. Oh no, it's the dreaded terminology alert. Changing the rows in a matrix into corresponding columns is called transposing a matrix, and we notate the transpose function with a superscript 't'. So this matrix is the transpose of the original coordinates. This is the transpose of the combined transformation matrix, and this is the transpose of the newest coordinates.
As we saw earlier, the original coordinates were in a one row by two column row matrix, which is also called a 1 by 2 matrix. But after we transpose the original matrix, we end up with a 2 row by 1 column column matrix, which is also called a 2 by 1 matrix.
Likewise, the transformed coordinates were also in a 1 row by 2 column row matrix, or a 1 by 2 matrix, and the transposed matrix is a 2 row by 1 column column matrix, or a 2 by 1 matrix. In contrast, the combined transformation has 2 rows and 2 columns, and thus is a 2 by 2 matrix, and the transposed matrix also has 2 rows and 2 columns, and is also called a 2 by 2 matrix. Now, because writing out matrices can be cumbersome, people often replace them with variable names. Matrices with only one row or column are usually referred to with lowercase letters that are sometimes italicized and sometimes not. And matrices with more than one row and column are usually referred to with uppercase letters that are also sometimes italicized and sometimes not. Out in the wild, you'll find additional notation styles, so just be prepared to be flexible.
Anyway, given these variable names, we can rewrite the matrix equation like this 'a' times 'W' equals 'b'.
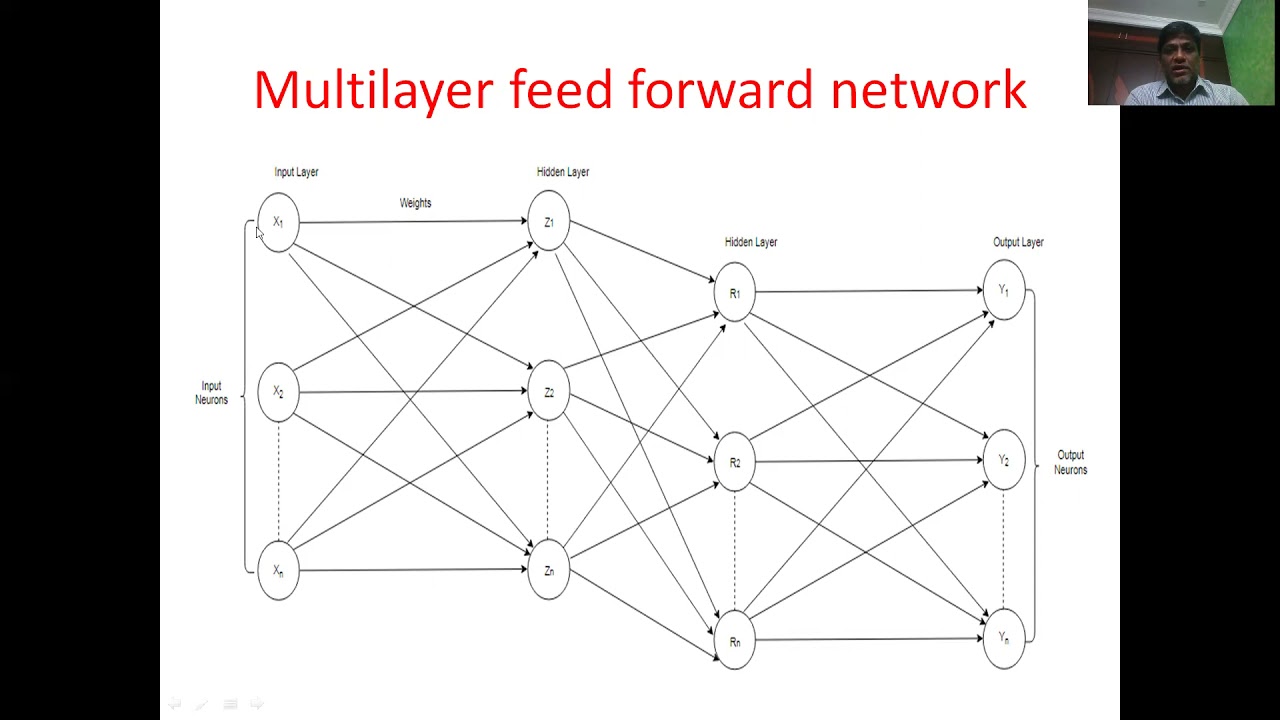
Or we can refer to the transposed matrices by simply adding a superscript 't' to each variable name and rewrite the matrix equation like this: the transpose of 'W' times the transpose of 'a' equals the transpose of 'b'. Either way we do it, we will get the same transformed coordinates. Note, we could have just as easily called this column matrix 'a' and called this row matrix the transpose of 'a'. Likewise, we could call this matrix 'W' and this matrix the transpose of 'W'. Lastly, this column matrix could be called 'b', and this could be called the transpose of 'b'. Thus, we could also write the matrix equations like these: the transpose of 'a' times the transpose of 'W' equals the transpose of 'b', or 'W' times 'a' equals 'b'. I mention these alternative ways to write the equations because out in the wild, you'll see all kinds of notation, so just be prepared to be flexible. Lastly, if we want to refer to an individual value in a matrix, like this -1 in the bottom left-hand corner of the matrix we originally named 'W', then, if the variable is uppercase, we convert it to lowercase and add subscript row and column indices like this. Bam! Now let's talk about how all this applies to a neural network. This neural network may look really fancy, but all it does is take two measurements from an iris flower, the width of a petal, which is this part of the flower, and the width of a sepal, which is this part of the flower. And with that information, it predicts the species either Setosa, Versicolor, or Virginica. Anyway, let's start with a petal that is 0.5 units wide and a sepal that is 0.4 units wide. The first thing this neural network does is multiply the petal width by -2.5.
Hey, wait a minute. Where did that -2.5 come from?
All of the numbers in this and pretty much every neural network come from something called backpropagation. And there's a lot to be said about backpropagation, so if you want to learn about it, check out the Quests. Anyway, then we add that term to the sepal width multiplied by 0.6.
And at the same time, this neural network also multiplies the petal width by -1.5.
Then we add that term to the sepal width multiplied by 0.4. Now, even though we are looking at these equations for the first time, they may remind you of the equations used to transform 'Squatch's ticket to see Taylor Swift.
Those memories follow me around.
In both cases we have two variables multiplied by numbers, and then the terms are added together. And just like how we converted the ticket transformation equations into a matrix equation, we can convert the neural networks transformation into a matrix equation, where we put the petal and sepal width into a row matrix and multiply them by a matrix containing the coefficients, or the weights, in a neural network.
Now we just plug in the petal and sepal widths, 0.5 and 0.4, and do the math by multiplying the row of input values by the coefficients, or weights, in the first column and then adding the terms, and then multiplying the row of input values by the weights in the second column and then adding the terms. And that gives us a 1 by 2 row matrix of transformed values, -1.0 and -0.6. So this first part of the neural network transforms the input values. The next thing the neural network does is add bias values to each transformed value. So that means we add 1.6 to the first transformed value and we add 0.7 to the second transformed value. And when we do the addition, we end up with a row matrix with 0.6 in the first column and 0.1 in the second column. Now we are ready to use 0.6 as the x axis coordinate for the activation function on top and 0.1 as the x axis coordinate for the activation function on the bottom. Now we run both values through the ReLU activation functions. Note, there's a lot to be said about the ReLU activation function, so if you're interested, check out the Quest.
Otherwise, just know that the ReLU activation function outputs zero or the input value, whichever is larger. Thus, because the input for the top ReLU is 0.6, which is greater than 0, the output is 0.6. And because the input for the bottom ReLU is 0.1, which is also greater than 0, the output is 0.1. Now the network has three transformations that it applies to the ReLU output. And doing the row by column multiplication and summation gives us this one-dimensional 1 by 3 row matrix. Then we add bias terms to each transformed value and we end up with the output values for Setosa, Versicolor, and Virginica. Bam! Thus, when the petal with is 0.5 and the sepal width is 0.4, this neural network predicts that the measurements came from Versicolor, since its output value is closest to one. So, now we've seen how this neural network can be written out as a sequence of matrix multiplication and addition. Bip bip bip bip bip bip bip. Now, if we call the row matrix, that contains the input values 'a', and call the first transformation matrix, which contains weights, w1, and the first row matrix of bias terms b1, then we can use 'a' times w1 + b1 as the input for the ReLU activation function. We can then multiply the output of the ReLU by the next transformation matrix, which will call w2, because it also contains weights. And then we add the final bias values, b2, to get the predicted species. And at long last, we've seen how to transform a neural network into a super compact matrix equation.
Double bam! Now to review, let's go back to the matrix equations we started with and see if we can make sense of them. This first bit comes from the PyTorch documentation for the nn.linear class. And we just saw that an equation like this corresponds to a part of a neural network that looks like this. This 'x' corresponds to the input values, and like we saw before, the input values can be put in a one-dimensional row matrix like this. This transpose of 'A' corresponds to the multiplication of the inputs by the weights and the sums of the terms. And all that math, the multiplication by the weights and the summation of the terms, can be accomplished by multiplying the inputs by a transformation matrix containing the weights. Note, the transpose 't' of matrix 'a' just means that nn.linear assumes the weights are in rows. But in order for this math to work out, they need to be in columns. Lastly, this 'b' corresponds to the addition of the bias terms to the result of the matrix multiplication, and that just means that we put the bias terms in a one-dimensional row matrix and add those values to the transformed values. Thus, this simple neural network multiplies and adds these matrices, and that corresponds to this matrix equation.
Thus, the nn.linear class builds a very common part of a neural network. And do you remember how early on in this StatQuest we made a big deal about linear versus nonlinear transformations and how a linear transformation means a constant change in the input results in a constant change in the output? Well, this part of a neural network and its corresponding matrix equation is a linear transformation. And now we also know that the nn.linear class gets its name from the fact that it performs a linear transformation.
Now, let's talk about this error message. Although there are some technical differences between tensors and matrices, they have a lot in common and we know that a 1D, or one dimensional matrix, is just a single row or a single column, but the function that generated the error was expecting something with at least two dimensions like this matrix. So the error just means we need to think a little bit more about the data we are giving the function.
Note, there's a lot more to be said about tensors in the context of neural networks.
So if you want to learn more, check out the Quest. Lastly, this is the equation for attention, which is used by transformers, the neural network architecture behind ChatGPT. Attention requires three matrices, 'Q', 'K', and 'V'. For example, given these three matrices, the first thing we do is multiply 'Q' by the transpose of 'K'.
And given these example matrices that gives us 11.7. Then we divide by the square root root of d sub k. And for the sake of this example, let's assume d sub k equals 2. So we divide 11.7 by the square root of 2, and that gives us 8.3. Note, if we had started out with matrices that had more rows and columns, we'd end up with a larger matrix at this point. And to be clear, attention is expecting larger matrices, and that is why these variable names are capitalized. However, we're just using row matrices because they keep the example as simple as possible and they work. Anyway, now we take the SoftMax of our little tiny matrix and we get 1.0. Note, this is probably the world's lamest example of the SoftMax function in action, but if you want to learn more about it, check out the Quest. Anyway. The last thing we do is multiply our tiny 1 row by 1 column matrix by 'V'. And that gives us these two values. And those are the attention values for the example matrices. So given these matrices, we might not know what attention means, but at least we can do the math. Bam? Well, if you want to know more about what attention does and means, check out the Quest.
Triple Bam! Now it's time for some shameless self-promotion. If you want to review statistics and machine learning offline, check out the StatQuest PDF study guides and my book, the StatQuest Illustrated Guide to Machine Learning at statquest.org.
There's something for everyone! Hooray! We've made it to the end of another exciting StatQuest. If you liked this StatQuest and want to see more, please subscribe. And if you want to support StatQuest, consider contributing to my patreon campaign, becoming a channel member, buying one or two of my original songs, or a t-shirt, or a hoodie, or just donate. The links are in the description below. All right, until next time, Quest on.
Up Next
28:25
Gradient Descent & Cost Function Tutorial for Linear Regression Python
@codebasics
805.9K views•2018-07-22

73:14
3D Computer Vision: Lecture 1 Part 2 - Projective Geometry
@cvrplabatnus8618
15.3K views•2021-01-20

17:33
Backpropagation Explained: Neural Network Optimization Basics
@statquest
732K views•2020-10-19

18:41
Neural Networks Explained: Math, Layers, and Learning Fundamentals
@3blue1brown
21.9M views•2017-10-05
Related Study Plans & Knowledge Roadmaps
Structured learning paths in Artificial Intelligence
artificial-intelligence
PINNs: Fluid Dynamics with PyTorch & DeepXDE
01Calculus & Fluid Dynamics Foundations
02Deep Learning & PyTorch Basics
03Introduction to Physics-Informed Neural Networks (PINNs)
+ 3 more learning modules
32h6 modules
Explore Roadmap
artificial-intelligence
Aligning LLMs: DPO, TRL & Custom Datasets
01Foundations of Python & Machine Learning
02Transformers and Large Language Models (LLMs)
03Aligning LLMs: SFT and RLHF
+ 3 more learning modules
24h6 modules
Explore Roadmap
artificial-intelligence
Federated Learning: PyTorch, Flower & Privacy
01Python & Machine Learning Foundations
02Deep Learning Basics with PyTorch
03Introduction to Federated Learning
+ 2 more learning modules
35h5 modules
Explore Roadmap
artificial-intelligence
Securing LLMs: Guardrails AI & NeMo Gateway
01Introduction to LLMs, Python, and APIs
02Understanding LLM Vulnerabilities & Threats
03Defending LLMs with Guardrails AI
+ 2 more learning modules
15h5 modules
Explore Roadmap