









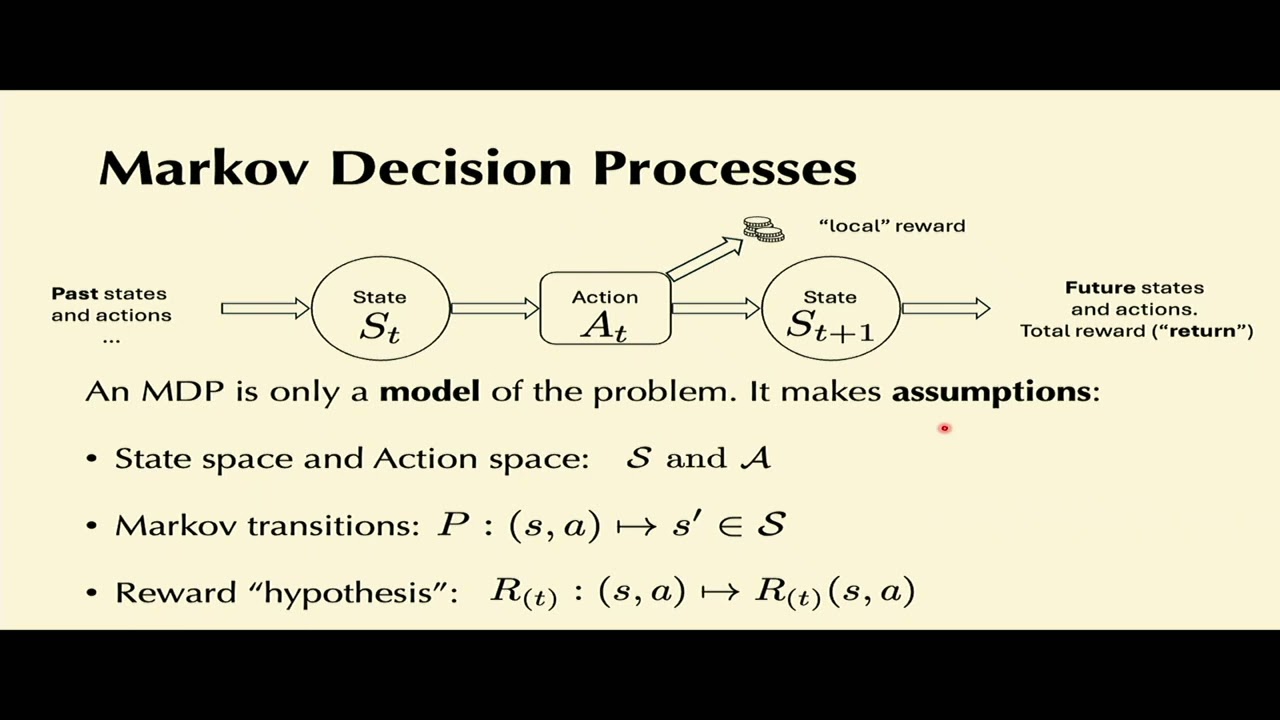





Markov Decision Processes (MDPs) model sequential decision-making under uncertainty using states, actions, transition probabilities, and rewards, where the Markov property ensures future outcomes depend only on the current state and action. The goal is to find an optimal policy that maximizes the expected sum of discounted rewards over time, achieved through value iteration which iteratively computes value functions V(s) and Q(s,a) using the Bellman equation until convergence.
Markov Decision Processes (MDPs) Explained | CS188 Lecture 8
Added:Basic probability theory, including conditional probability, random variables, and expected values.
Classical search algorithms (such as BFS, DFS, and A* search) and how to represent problems using state-space graphs.
The fundamentals of utility theory and the principle of maximizing expected utility in decision-making.
Policy Iteration, as a distinct and often faster algorithm for computing optimal policies compared to Value Iteration.
Reinforcement Learning (RL) foundations, specifically Q-learning and Temporal Difference (TD) learning, where transition probabilities and reward functions are unknown to the agent.
Partially Observable Markov Decision Processes (POMDPs) to model environments where the agent cannot perfectly observe the current state.
Deep Reinforcement Learning (Deep RL) to scale these decision-making algorithms to complex, high-dimensional state spaces using neural networks.
125.7K views1.1Klikes1:07:10Original Release: 2013-02-15
okay so then let's start with lecture for today today what we're going to look at is market decision processes this is actually the scenario we're going to be looking at pretty much the entire lecture it's going to be our running example a robot it's just walking around in some space there's a really dangerous fire pit don't want to get in there but there's this beautiful diamond on the other side that you want to get to now robots aren't super reliable if you try to make a move they might not succeed and that's we're going to deal with how do you plan optimally when your actions are not deterministic and the outcome is not you cannot predict it you can only have a distribution over the outcomes okay so here's the scenario your robots trying to get to that diamond but there is some danger how do you make the right decision in those situations so here's a view from the top formalizing this a little bit the agent lives in a grid draw walls that block the agents paths sometimes so here we have a wall it's a state the edges cannot be in this case our 11 grid squares the agent could be in and one it could not be in so there's 11 possible States and 2 are special this one is marked with a plus one it means if you visit that state and then you take this special exit action you get a reward of +1 and this is also very special visit this state only one action is available to you you can move out of the pit the only action available to you is to just exit the game and you get a minus 1 ok so there is some noise here 80% of the time you succeed if you try to go north 80% of the time you'll go north but 20% of the time you won't succeed and then 10% of the time you'll not be run off to the left 10% of time off to the right from where you were trying to head if you try the head out of the board or into a wall a successful way of moving north from over here the 80% probability makes you bounce against the wall and stay here so that's how the dynamics of the system works you try to leave it or into a wall you stay in play 80% chance there's still 10% chance that you would move off to the side okay then the way we define the problem here is there's not just utilities at the end but at every step it's possible to get some reward positive or negative for what just happened and for example you could have a small living or worth which means as long as your agent is alive and hasn't exited the game maybe there's a reward of minus 0.1 or something what would that do that would encourage you to exit so what that would mean is that now you like to get to the diamond quickly because as long as you're not there yet you're incurring a negative reward so that's what it does to have a living reward okay the goal will be maximize the sum of rewards that you accumulate over this process so this is the goal it's similar to the goals we looked at in previous lectures you have the utility to try to maximize it but now you utilities the sum of the rewards accumulate over time and that's where you try to maximize okay what are the actions in this grid world let's say you have a deterministic world the extreme case you start over here you ask for north you end up in this world over here the switch today is that if you ask for north from this initial State you have three possible outcomes you can end up in the fire pit over here you cannot up north the successful action this is 80% chance this is 10% and this is 10% this looks a lot like expecting max right we've seen this type of thing before you can think of these as you commit to an action after committing to an action you land in this chance node which then determines what happens to you so in some sense we've already seen these types of problems but today we're going to look at a different way of solving them and we're going to learn how to deal with the case when you're acting in for infinite horizon so the game never stops potentially how do you deal with that that means your tree is infinitely deep we're also going to see how in the situation's we're considering here we can do something much more efficient than expecting max okay so how do we define an MDP or a Markov decision process there's a set of states we've seen that before set of actions we've seen that before now to model the stochasticity we have a transition model T si s prime what this is encoding is the probability if you start in state s took action a to then land and status prime so another way to write this is to write this as this is really the same thing C as a as prime is the same as the probability of landing in status prime given at the previous time you were in state s and took action a that's how we encode the stochasticity then now instead of having just a utility at the very end of the game we have rewards at every step and this reward can depend on everything related to that step the state you were in before the action you took and the state you land in then sometimes you can simplify this so you'll see some treatments where they'd say the reward just depends on s just depends on S prime or just on SN a those are just special cases where the reward function is simplified you have a start state very often and maybe you have terminal states but we'll see that it's also possible to work within the MDPs where there are no terminal states and your thing keeps running forever so these are non-deterministic search problems we actually know how to solve these but not in the efficient way that we're going to look at today and so we'll have a new tool very soon to solve this way so what is marking about this Markov decision processes in general whenever in artificial intelligence and even beyond you see the word Markov it refers to this guy over here but really what it means technically is that you somehow have a sequence of things and you associate indices with these corresponding to time for example and that whatever happened in the past is independent of what's going to happen in the future if you know what the state is at the current time so you have a separation when you when you know the state at the current time history won't affect anymore how things will be in the future so what that means is very similar to search where once you know which state you're in you don't need to look at where you came from to know where you would land next if you call your successor function same thing here the transition model only depends on the current static current action not on past states and past actions so in full generality you could have this the next day depends on all past states and actions but if you have the mark of assumption in place then this simplifies to this expression over here okay that's just an assumption if that assumption is not true and you say oh I have this state space and actually the next state doesn't just depend on the current state in action but also on the previous state and previous action there's actually very simple fix the simple fix is that you redefine your state space say my old definition of the state space wasn't really right because it didn't make it Marco so I'm going to include the past state in the past action into my new bigger state and now in this bigger state space you're able to model it as a market decision process now the catch of course is that you want to keep your state space and action space small so you prefer to put as low as possible in your state while still having this Markov property okay what's the goal in this whole MDP framework the goal is to find a policy this is different from what we've done before before let's say in search a start search what you get back is a sequence of actions but here since we don't know the outcome of our actions we cannot just restrict ourselves to computing a sequence of actions we need to know for every possible future state that we might visit what the right action would be if we ever prescription that prescribes our every state what action we should take that's a policy anything that prescribes actions for every state is a policy if you this will be one or sometimes a few policies are optimal in the sense that they maximize the expected reward you will accumulate and that's that's the policy will be after the one that maximizes expected sum of rewards so so what is the policy formally it's a function from States to actions and a defense it essentially defines what we know from the very beginning is called a reflex agent so once we are solving an MVP and we're done solving it what we get out is a policy if we just store that policy we now have a reflex agent and we don't need to remember anything else and that reflux agent will actually be rational and do the optimal thing so we'll get out is this policy that we'll use okay let's look at a couple of optimal policies here's the first example remember it is the firepit scenario minus one over here plus one over here everything else you get a minus 0.01 reward for a transition that's a living reward that encourages you to try to get to the exits if you solve this particular problem a naive way would be to consider all policies right and you compute for every possible policy what you expected sum of rewards is you can then see which one achieves the highest expected sum of rewards and for this setting the one drawn here achieves the highest expected sum of rewards so let's look at some properties here what's going on here we go up makes a lot of sense because you probably want to avoid having bad luck getting into the fire pit go up here to the goal that all seems to make sense now what's going on over here well you try to stay away from the fire pit so you go around this way how about here what's happening they're just trying to run into that wall why would that be well for think back to the dynamics of the problem 80% chance of succeeding at your action 10% chance veer off to the left 10% chance veer off to the right so by heading into the wall you will never fall into that fire pit you'll usually just stay in place bump into the wall stay in place but 10% of the time you I should move north and end up where you want to end up so take a long time because only happens 10% of the time but that's in this case optimal way to tact here's another one the living room word here is a little more negative so you want to get through your exit stage sooner so what happens now is that most things stay the same but look at this one over here now the Altima thing is to move up why is that well now we have a small chance of landing into the fire pit where they try to move up 10% chance but the upside is that we're not stuck in that state for a long time before we might get lucky and finally move up so there's a trade-off here where on the average here yes sometimes you land in the fire pit but at least when you don't you get to this state pretty quickly whereas in this case you're going to be stuck here usually for a long time and then only after a long time I turn up there or there and then be able to make it pretty likely to the good exit state yes okay that's a good question while you're acting you already get some rewards and you could say do we keep track of how much reward you already have in the MDP framework we do not keep track of that we just consider what's coming in the future so your reward is because your reward is only allowed to depend on the current state action in next state and you want to maximize expect some of rewards it doesn't matter what you had in the past you just want to maximize what you're going to get in the future [Music] no we wouldn't it actually wouldn't in this setting because whenever at a current time you're looking at this problem it actually looks the same you have this imminent future ahead of you and if anything and you'll just have the same optimal policy no matter how long you've already been acting in the MDP here's another example we crank up the living reward even more now what happens is that from here you know she tried to go this way more risky path but you have to do that in this setting to be optimal because otherwise you'd be spending too much time before you get to the plus one and so the trade-off is now that you're willing to take the risk and hopefully you don't fall in the fire pit and get the bigger word at the top crank it up even more where you get now you become suicidal the living your word is hired on the end reward so even when you're here you just jump into the pit your glob is so bad all right any questions about what policies are and what the MDP setting is yes okay what the squares are the squares each square denotes one of the states that you could be in so the set of states in this case there are eleven possible states shown to you each of the squares is one of them in general the reward function depends on state action and next state but here it's a simplify their worth function that only depends on the current state and for the current state if you're not in one of these exit states then for the current state the reward will always end up being defined as whatever we define down there so for every state you get for example - to exit for these here where you would get plus one and minus one and exit the MDP so to actually make it fully formal if you want to see all the states it's actually one more state here called the exit state and from here you can go there from here you can go there and the minus one and the plus one you get on that transition to the exit state yes what exactly is RFS is something that we give just like in previous lectures we assume you give a utility function to your agent and the agent then optimizes it we assume here that we specify their worth function whatever we think is important to score high on we put into the system and then the algorithms we'll see will spit out a policy that does the optimal thing with respect to the reward function that we choose pi pi is how we denote the policy so we use PI or PI star if it's the optimal policy so and the way we draw it is by these arrows because a policy specifies an action for each state and so by drawing an arrow in each state in this particular MVP we can specify the policy we're talking about yes that's coming we haven't covered that yet but yeah that's really important to find out how that works yes because different things are optimal depending on what the living your word is living your word essentially penalizes you for how long you're acting in this MDP before you hit the exit state and so the more negative it is often it will come off multiple take strategies that are riskier and sooner get you to hopefully the right exit state but maybe the wrong one yes correct yes transition to the exit state takes exactly one time step and it's your only action available in the pit or in the diamond State yes you can have infinite rewards in there okay well then we'll get some pretty weird behavior if we throw some infinities in there we're not going to look at that but I'm happy to chat with you about that offline after lecture okay so we know what MVPs are we know what policies are let's now look at another example of an MVP just like search problems aren't always shortest path problems and the piece aren't always Grid worlds with fire pits and diamonds here's another example a racing example very simple example you have a robot car you want to travel far and quickly stay idea and your car can be in the cool state where the engine is safe in the warm state where you're getting in the risky zone and overheated where your car broke down so here are the three states you could be in and your actions available to you are either to go slow or fast and then you get the natural behavior if you go slow in the cool state your car engine will stay cool then if you go fast in the cool state you might be unlucky with 50% chance your engine gets warm 50 percent chance you stay in the cool state if you're already warm slowing down 50 percent chance brings you back to the cool state 50 percent chance keeps you in the warm state if you go fast in the warm state you're guaranteed to go to the overheated condition where you just break down okay so this one here is really what we before have as our exit state right at that point things are over you're always stuck in that one nothing happens anymore okay then we need to give rewards to make this a meaningful thing so we'll get double the reward for going fast compared to slow for example one for slow two for fast so there's some encouragement to go fast but you want to be careful about not breaking your car down so plus ones on the slows and plus twos on the fasts actually it's a little typo here it should be plus two all right so that's the MVP oh and then one more here once you hit the exit state this this was actually the transition probability the exit state we give minus ten for the transition in here so the fast here gives you plus two but fast here gives you minus ten because you're exiting that's just a definition this is how we define our problem we models your world well then you're going to find a good policy with the techniques you'd cover if it doesn't model your world well then you need to define a new MVP that models it better okay now let's see if we can solve this we've seen search trees before we've seen that this is very close to expect a Mac so let's see what we can do you would start in the cool state let's say you get a choose from two actions that point you don't know what's going to happen so you hit a chance node from that chance node that mystically you stay cool if you pick slow but you have a 50/50 split between a cool car and a warm car in case you picked fast this was fast this was cool and then after that this continues and so this tree will keep going because we assume we play this game forever until the car breaks down so this is what our tree looks like so we could in principle solve this would expect to max but there are a couple of issues all right one issue is that the tree keeps going so it's infinitely the another issue which is not too bad is that now the utilities are not sitting at the bottom but the utilities are sitting on every transition so you need a slight tweak to expect the max algorithm to add up whatever happens on the transitions rather than just propagating a number from the bottom that's not too hard to do the hard thing is to deal with the fact that this tree goes infinitely deep and the other pattern that we're seeing here is that we see a lot of repetition even in just step two we already see a lot of repeated states and they are really repeated because from anytime you see a blue car from their own is infinitely long so it's identical no matter which blue car you see is the identical situation so expecting max will do lot of repeat computation because it's handling those all independently so the look at this a little more closely we have an MVP we said how does this relate to expect the Maxwell and both have states then you have a stochastic transition in your MVP that means you land into some chance node and then from that chance node you land into a next state with some distribution we'll define something new a new concept today something called a queue state a queue state is a state where you're kind of in a holding pattern you were in a state a normal state you picked an action you haven't made the stochastic transition just yet that's the name we'll use for these chance nodes when we work with MVPs there'll be queue States now the transitions that we define for an MVP are sitting over here that's where the probability distribution is sitting after your chance node and then the reward is also sitting over here it's sitting on that transition state action and next state determine what the reward is going to be okay so we can map an MDP to an expected max search tree we just have some downsides in working with them that they're infinitely deep and we have a lot of repetition and we'll see how to resolve that before we do that because there is a difference here that we look at sequences of rewards rather than and we try we say we're going to add them up rather than just one utility at the end how should we really deal with these sequences of things that pop up let's say your robot and you're faced with two paths one path you get a different colored diamond in every step the other one you take equally many steps we only get all the Diamonds at the end what will you go for you would go for the left one most people would go for the left one especially if there's any uncertainty right you rather grab things right away rather than waiting till later you never know what happens also more formally if you get something that's worth something you get it early maybe you can invest it and make money of it or if you get it later well then you only get it later you haven't been able to make money of it so what do you prefer we prefer the left route that's the one that we think is more with me to give numbers to these things let's say you had a sequence where it was one to two versus two three four what would you prefer now now it's trickier actually right let's take a look we have some numbers two is higher than 1 3 is higher than 2 4 is higher than 2 actually not too hard we pick this one here but if you have a choice between now and later in this one here do you want the one here or the one here we pick this here because you get it sooner so we want to formalize that how can we formalize that our agents would prefer getting rewards earlier rather than later the concept we'll use is something called discounting and the idea here is that we do something very similar to imagine you were able to accrue interest think of your rewards as money and imagine you build a crew interest are you to get an exponential growth of your money over time and so we'll do the equivalent here where we say things we get later will not get the same amount of growth so I have to discount them they're worth less well if they exponentially discount them because they're worth exponentially less because they don't get that exam exponential growth so formally how does that work let's say you get a diamond now it's worth 1 the next time it's not worth 1 anymore it's worth gamma and gamma is our discount factor and much later 2 steps later in this case it's worth gamma squared and so forth so often gamma will be something like 0.9 or you can slowly decay over time how much things are worth okay so how does that look in our expected max trees well that means that what we're adding things up step by step we're actually not just looking at the reward but we're waiting the reward by the discount factor we start up here this is the start state here we multiply by 1 here we multiply by gamma and here we multiply by gamma squared they want to have multiple advantages but the first thing for now is that this allows us to give a behavior where you try to get rewards sooner rather than later something we'll see later is that it also helps you get algorithms to converge so let's look at a discount factor of 0.5 what do you end up with if utilities sequence 1 2 3 you get 1 times 1 0.5 times 2 and this is equal to 0.5 squared times 3 okay fairly straightforward just an adjustment to how we add up rewards so 4 1 2 3 versus 3 2 1 we know 3 2 1 and this scheme will be better assuming your pajamas smaller than 1 if you pick your gamma larger than 1 what that means is that you now prefer rewards later rather than sooner ok can we give another justification for why we would want to work with this exponential discounting there's many ways to say that later rewards are worth less than earlier rewards we pick this exponential discounting where is that going to help us well one way that helps us is that let's say you willing to make the assumption that you want your preferences to be stationary that means if you could get if you have to choose between a sequence of rewards today there were two sequences of rewards presented to you today you get to choose between those two sequences and then tomorrow you again get presented with the same two sequences you get to choose again stationarity means that you would choose for the same sequence no matter what day you're presented with any of the sequence asks you get something today something tomorrow something the day after stationarity means that no matter which day you get presented with the different choices of rewards for today tomorrow day after it always picked the same sequence it turns out if you're willing to make that assumption it's not a very strong assumption there are not many choices of how you can combine the rewards you're actually stuck with just these two options so assuming of stationarity over sequence of rewards which formally means that if you're presented with a sequence a 1 a 2 and so forth you preferred over B 1 B 2 and so forth then if in addition you initially get R in both cases you'll still prefer the one with the A's then you have stationarity if you want to assume that then the conclusion is that your utility function has to be an additive function of the rewards and the only freedom you have is choosing this discount factor gamma few choices are shown but in some sense is just one choice because if you said gamma equal to one the first one is equal to the second one now one of the beautiful things about assuming stationarity is that what that means is what we discussed a little earlier is that if you find your optimal policy the optimal thing to do that on what policy will be the same no matter when you use it today tomorrow day after and so forth so you don't need to have an optimal policy for every possible time you can have one optimal policy and that's it ok let's do an exercise on this what's the quiz here 3 quizzes in 1 we're given a grid world there are five possible states ABCD and E if you are in any of these states you get to choose from east-west for BCD also for a and E but if you're an A or e you have an additional action available to you which is to exit there is one more state which is the exit State and that one is available from here and from here and that's what gives you the reward so if you start in state e in one step you could take the exit action get a reward of one ok now the transitions are deterministic just to make our computation easy and let's think about Oh these things aren't showing up right so these are gammas for gamma equal to 1 what is the optimal policy so what I'm asking here is for each of these five states what is the right action to take if gamma equals one quiz 2 the question is if gamma is 0.1 which means you have some discounting then for each of these states what is the right action to take to be off and then the last question is well is you find the value of gamma such that if you start and state D going east and west are equally good for you now you get the same expected sum of rewards where do you go east or west alright let's take two minutes need to try to figure these three questions out and then let's see what you got [Music] sure precision in preference life is in dictionary ordering life for stationary parchments this one I'll a dictionary ordering for the murder dictionary I don't know what that is mom like yeah first like you know if you order how to order in dictionary oh I see what you're saying um that would be a stationery preference but it wouldn't give you one number so you don't still have to somehow turn it into a single number I mean like you're you're defining a relation you're defining a preference relationship you say between different outcomes here is my preference relationship what that's saying is that what we saw last time you can always turn a preference relationship into a utility function what I'm saying is we turn a stationary preference relationship into a utility function you're gonna end up with utility functional baptized utility function assigns a single number to every possible outcome and so and we saw last time that's always possible if you're rational all right and so you define a rational set of preferences you haven't yet defined a utility function so that's an additional step once you've done that you'll see that it will be in that format those two like forms are dividers Bobby you wanna use yes mm-hmm yes another part of it though is that your preference relationship that you define is actually not you cannot break it down the same way and she wouldn't even work because we want a utility to be a combination of the utilities of each one of them and yours would be not a utility that depends on just first second third but it with them in all them at once you couldn't decompose it right so we want something that's a function of utility of the reward at time one utility of the reward at time two utility of reward at time three yours wouldn't be able to do this yours would yours would have to be something of this type which we're not allowed to do we need to have utilities with each individual reward that's another constraint [Music] [Music] all right let's see what we found let's start with the first one quiz 1 so for quiz 1 who is a suggestion I hear something always west always west I agree what would that do for you there is no discounting so always west would reach the a state where you would then take the exit action get the reward of 10 so no matter where you start you go west that's the best thing you can hope for right so here we have the all West so we look like this and here you would exit how about for the second one this counting of 0.1 what's the optimal policy there say that again head west for B and C so we go west here and here east for D and then here you would exit presumably and here you would exit why is that let's do a little competition here if you start here the 10 is closer by the sooner you get award the better so obviously moving towards the 10 is going to be the winning strategy here they're equally far away the 10 is equally far away a bit a higher reward so moving to the 10 you'll get I'll take one you'll get 0 then you'll get gamma x 0 and then you'll get gamma squared times 10 which will give you a total of 0.01 times 10 which is 0.1 if you had gone the other way well then instead of 10 times 0.01 you've gotten one times 0.01 so that's obviously worse and here what happens over here if we were to go this way the way that wasn't suggested we would get gallon to the third times ten instead of gamma squared times 10 because it's taking one time step longer which would be 0.01 we go this way we end up with 0 and then gamma times 1 which gives us 0.1 so the better thing to do is to go east from there because of the discounting you're closer to the 1 and it happens to count out that way such that that's the best thing to do how about the last one quiz 3 is there a gamma 4 which east and west are equally good where you state D so when you're over here there's a choice of gamma where they look equally good say it again root of 10 is a suggestion so let's try to compute this let's see how we get to that right and see what it is what does it mean to be equally good it means that both options give you the same discount of sum of rewards we saw if we go all west we get gamma squared times 10 we go all east we get gamma times 1 we want those to be equal that means both options are equally good so that correct no gamma to the third here gamma to the third times 10 gamma times 1 simplifying gives us gamma squared times 10 equals 1 so we have gamma equals square root 1 over 10 it seems it's that correct okay so at that gamma value it'll be equally good if you're lower gamma that means you need to get a reward sooner you go east higher gamma value you're willing to go all the way west okay great what about things that last infinitely long the car example you could be driving that car forever what's going to happen well the big problem there potential problem is that we out of these rewards when we get infinity and then if we have multiple infinities they become really hard to compare so one solution is to say to avoid these infinities let's use a finite horizon so you redefine your MVP do not last completely long but say after maybe 20 steps it's over that's like cutting off your search tree and expect Emacs saying that's the end of the game it's one solution the downside of that is that if you really care about looking far ahead and getting a reasonable policy for acting for a long time you will need a very deep tree before you can cut off then the additional thing there is that when you do this you don't get a stationary policy because now really what you have is that what you might want to do depends on how much time is left right it is one time step left you might want to do something different than when there is five time steps left imagine you're one step away from the one five steps away from the ten the number of time steps away will affect what you're willing to do so now you don't just have action for each state for now you have an action for each state and each amount of time left that you need to store so it gets more complicated in terms of what you need to store another option is to use discounting and this is also one of the reasons people often use discounting even when in fact you might know that it's not going to last infinitely long maybe it's going to last a thousand time steps you say approximately that's like doing some discounting with a factor of 0.999 okay I know it's and if it's some kind of effective horizon when you do discounters because it's as if things in the future don't matter so much anymore right so if you have utility function that discounts the infinite sum becomes bounded by the maximum reward divided over one minus gamma where does this come from this is some T equals zero to infinity gamma to the T which is equal to 1 over 1 minus gamma so gamma is smaller than 1 strictly smaller than 1 you have a bound and you know that this infinite sum actually sums to something finite and so you don't have issues with infinite rewards that are really hard to compare so for example one rule of thumb could be let's say you want to design a control policy for a thousand time steps all right and you could a 1000 time steps that would be a lot of policies to store one for each time step I don't want to do that I'll pick my horizon such that it seems that I rise number thousands things don't really matter much anymore you say well I want gamma to the one thousand to be maybe equal to something really small 0.001 that's how little I want things to matter from then onwards and then you can compute a gamma that corresponds to this and as a consequence you now can run something with a stationary policy standard MVP setting with the infinite horizon so it's a little trick most people use the infinite horizon just for this convenience and you just have to back out from your horizon what gamma you might want to use okay so we said on infinite things they'll some do something finite if you have a very special case where you're guaranteed to hit an exit state no matter how hard you try then you can also get away with actually not worrying about this but that's kind of a special case okay so here's our MVP recap we have market decision processes have states start state actions a transition model this is new rewards defined for state action state transitions and a discount this is good because it models the idea that sooner is better and it allows us to work with infinite horizons and then what we want is a policy and what we optimize we want a policy optimizes the sum of discounted rewards so how do we solve for that how do we find the right policy given a specified MVP actually let's take a couple minutes break and then let's see how we solve them alright let's restart so let's see how we can find our policies one question that came up during the break that I want to highlight everyone is why do we always think of policies as deterministic couldn't it be that you want a policy where you say I'm going to randomize and give instead I'm going to cross the pó in and do a coin toss and then see what the outcome is and basically not take an action sure that's a policy - so why are we not considering them the reason we're not considering those is because it turns out that optimizing expected sum of rewards which is what we're going to do yup there's always an optimal policy that is deterministic that doesn't require any coin tosses in fact usually there will only be one off more policy and it will be deterministic so that's the reason we're not focusing on stochastic policies because then we never need them to be optimal but they do exist and you know it can sometimes come up they can think what will happen with a stochastic policy we might see one in next lecture just to mix things up but we don't really need them we just want to find out more policies okay so what are the optimal quantities we're after in this MDP we have this infinite three so we look at some point in the trader some state s we're going to define some new quantities that will help us solve for the optimal policy and the expected sum of rewards that we're going to get from there so V star s is the expected utility starting in s and acting optimally so this is a vector with an entry for every possible state a number for every possible state we don't know yet how to compute that vector but that vector is of great interest to us because it's telling us how good each state is if you did the optimal thing from that state as this is the expected reward you would get then for the chance nodes we define something very similar and what that is is if you are in state s you already took action a so you're now in a chancellor you don't know yet what the outcomes going to be there's going to be a distribution over outcomes in general the expected sum of rewards that you're going to accumulate from then onwards assuming you act optimally from then onwards the action a might not be optimal this is defined for every action a and so only one of them will be the optimal one the assumptions that after taking ans you act optimally from then onwards what's your expected sum of rewards that quantity is defined as Q star si obviously if we have Q star si we have a solution to the problem because now we can say oh well we have Q star say for our current state s all we need to do is to check which one of these actions as the highest Q star si because that's the one that will lead to the highest expected sum of rewards take that action then we'll see where we land we landed a new status Prime with a new status Prime we can again look for all actions what is Q star s prime a and see which one is the highest one and keep repeating this but we don't know yet how to find Q star but if we can then we have a solution to the problem so pi star s is the optimal action and we know that pi star s will be equal to some people see more in the future the arc max over a of Q star si what does that expression mean that expression means that we look at Q star si which is a table of numbers as is fixed with very a so if a one-dimensional table of numbers for each in sensation of a we have a number we check which one is the maximum number that's a number but we then don't take out that number we don't take the value out but then we check which action achieved this value and that's the arc max for this type of expression that's what it means it's not the value at the optimum but the action that achieves the optimum that's why we have that's why in the arc up front that's what indicates that we get the action out not the number okay so that's what we're after let's take a look at what these quantities look like here's the optimal value function V star s in our pit diamond grid world what do you see here well one thing we see over here is a one that's not too unexpected from there you would take the exit action get your reward of one and be done in the pit the only thing available is the exit action your ORD of - one and done and if nothing happens well that's your expected sum of rewards and then here we see that we get a pretty high expected sum of rewards because it's likely that if we do the optimal thing which could be moving over here right the ultimate thing would be to move to the right then we would get in the next time step a reward of one but it might not succeed we might end up somewhere else so we get a little less of course than in this terminal state and we see this kind of decline of values because it takes more time to get to the exit state when you're further away all right so that's the pattern we're seeing or kind of see this wavefront from the exit states out to the other states all right that's our optimal value function don't know yet how to get it but that is what it would be if we were to compute it here is the optimal Q function so this is actually showing four values in each state Y or each state where we can choose via north south east and west y is showing four value as well as the Q function we could have taken any of four actions so these four possibilities for each state and we store the Q star value for having taken that action so for example here we see that 0.85 is the Q star value over here going north as 0.77 west 0.66 and sound 0.57 so we realize from these numbers that going east is the optimal thing to do in that state not surprising but these Q star values actually tell us that it tells it that's the right thing to do something that might be a little surprising is the number over here minus 0.6 right you might say well is this if this is 0.85 and it's trying to get into the diamond state with a reward of 1 why isn't this minus 0.85 well the reason this is not minus 0.85 is because if you were to take the action East which is admittedly the worst option you have available to yourself but there's an expected value for that there's a chance that you veer out north or south after you've done that when you compute your Q star value you assume that you'll be acting optimally from then onwards so 20% of the time actually wouldn't land in the pit you're lucky and goes somewhere else and from there you do the optimal thing and so likely we wouldn't end up in the pit so an expectation you're not as often landing in the pit if you go east here and from then on act optimally compared to East here and then acting optimally because if you fail here to go east well if you ended up going north you would stay here and you would then do the optimal thing and try east again you ended up going down here you do the optimal thing and move back up so in the state next to the diamond if then something went wrong you would do the almost thing from that onwards which again gives you a high expected reward whereas from the pit state if you didn't make it in that East action failed then again you would do the optimal thing and so you would avoid the pit most likely ok so that's how we interpret these numbers we can also read off from this data over here was the right thing to do starting the bottom left was to go north because this is the highest number out of the four numbers in that state by only one number in each of these states because they only have one action available just the exit action ok so that's what we're after how do we compute them we'll first start with a definition that's recursive it's not going to allow us to compute them yet but give us some insight in what they mean so is the expected utility under the optimal action is what we're after right we can say well the optimal thing optimal the expected utility V star s is the best available in s overall actions right that's pretty clear that that's the best you can do then you can do the same thing here this one requires a little more work q star si what do we see here if you took your action a already from state s what happens then with some probability you land in s prime and there are different nest primes let's consider one s Prime for now let's consider your line in a particular s Prime you would get a reward RSA s Prime and from then onwards you would act optimally what that means that you get on expectation v star s Prime from then onwards but that's happening one time step later that you get an expectation V star s Prime because it's happening one time step later it gets discounted by a factor of gamma now this was assuming we landed in state s Prime we're in a chance look we don't know yet where we're going to land so we have to sum over all possible next States s prime and then wait by the probability of going there this way to this way that sum here this waiting here is what happens in this expected node here it's waiting the branches the reward is sitting on the transition so you went to s Prime the reward is sitting right here for that particular transition for a particular s Prime and then this Status prime would have some value of V star as prime associated with it and you would get gamma times that because it's a time step later before you start accumulating so now we can compute V star if we know Q star we can compute Q star if we know V star we can compute them as a function of each other we can't compute them yet from scratch I'm going to take your question later so to compute V star without involving Q star which is often down to is you just do a substitution we had these stars this max here well we have an expression for Q star we fill it in here then we get this expression over here if you do one thing in preparation for the next three lectures it's to look at that equation and try to understand exactly what's going on in that equation that equation will come back on pretty much every other slide in future lectures the future three lectures you want to really understand that notation understand what's happening there that's called the bellman equation it's a recursive definition in terms of itself so we don't know yet how to find a V star but we know that this is a property it satisfies okay so yes so suggestion here is why not randomly assign some values to V Star and then iterate this process that's a process called value iteration and we'll but we're about to see why that works so that's where we're after yes that's the right way to think of it let's see so what does expected max do expect the max look at this looks at this 3 3 could be a very big tree so it's kind of expensive what's not good about it well if you look at it this is the same as this is the same as this as this as this as this as this this one here here and so forth so you have so many repetitions if you just ran straight up expecting max you'd have a lot of repeated work and it'd be infinitely deep think back to search we did something like graph search instead of tree search to avoid repetition when going down a tree we're going to look at now is actually something very similar to graph search but it's going to be structured bottom-up we're going to work from the bottom to the top rather than cashing things which is affected what you're doing graph search okay so repeated states are a problem we'd want to compute each of these quantities only once because we know that they're the same so why would we do it many times the key intuition here is that because we do discounting things really deep in the tree don't contribute a whole lot and that's what's going to make this work so what we'll do to exploit that intuition is to think of time limited values we'll say let's consider only a finite amount of time and cut up the tree there so define vks not V star VK has to be the optimal value of s if the game ends in k more time steps so just K steps left what does that mean well that's a depth K expecting max 3 if you can solve that depth K expect to max 3 you're done you found VK s it's the same thing all right so depth to here solve this depth to expect the max tree and this will give you if you do the expect max competition you get v2 that particular state at the top all right that's our starting point this is our new quantity VK of s that we now know what it means it's expensive to compute because we have to run expect to max for this depth k and then we do it for every state but in principle we could let's look at what these look like for this grid world here def zero that's a three that's essentially an empty tree you'll get zero rewards total zero everything zero what happens for depth one left one well for this state here taking the exit action will give you a word of post one here minus one those are the only actions available there none of the other states have rewards accessible so you'll get for depth one it'll look like this now for depth two will see that this stayed here now because you have a depth of two we'll be able to accumulate on expectations some reward this one here depending on exactly what you're living reward is might either dive bomb into that pit or might move up or to the wall so we'll see what happened here it decides that moving up is the right thing to do actually besides moving this way is the right thing to do so as a reward of expected of zero the only one that's nonzero that's new and k equal to is that one there in two steps you get the plus one later it's discounted that's why it's lower it's also lower because your action might not succeed and so as two factors coming into play why it's not equal to one there with a lower number okay keep going and we see that this kind of spreads out over time and after six steps we actually get a value if we will get to act for six time steps our expected reward down here is non zero how about if I get to Act seven steps will this value a change will it stay the same they'll change why is that because it'll now get a reward only if every action is successful but if one action fails and it has seven steps then it could make up for that failure if it's lucky and still get an extra rewards we get something like now we get point five eight instead of 0.34 after seven we can keep repeating this process in our heads building these expecting max threes that are deeper and deeper and we can see what happens to these values at k equal 100 this is what we get and it's actually converged if you keep going I should not get anything different okay so that's what these values V stark VK are we can build them up and what it does is in some sense we look at this big expect to my extreme we're going to now see where are these values appearing at the bottom here what is happening there we just have three types of states cold warm and broken and even though they expect the max 3 has many things we will only need three values one for each state for zero time steps left over here again just three different states one time step left and so we can compact this expect to max 3 which has big branching into something where in each layer we only have 3 values to compute because they're always repeated it's always the same state so that's really what we're after now is how can we now start at the bottom and first compute this one here which we know how to do and then work our way up so this value iteration start from the bottom work your way up this is the algorithm you start with v-0 this is a vector for every state as there's an entry and you set it equal to 0 because 0 time steps left no matter what state you're in we expected some rewards if your act ultimately is still going to be 0 then that's your initialization then assume you found already what VK S is for all states s this is how we can compute VK plus 1 s what is this computation this is that bellman equation again it's saying I'm computing for a state s we have multiple actions available and I'm going to pick the optimal ones I'm going to maximize over different actions whatever they end up giving me on expectations and once you pick an action you land in a chance node for a chance node there's a distribution over where you land next and that distribution is weighted by TSA s-prime they have a weighted sum and you count in the reward you get for the transition plus well you get in the future which is discounted by a factor gamma this is the again that equation that we really want to understand that we'll be using for three more lectures it's recursively defining VK plus 1 as a function of VK and the model that we have for the MVP okay that's not too hard to compute that's just a bunch of expected max computations to go from VK to VK plus 1 so we're done all right we can compute VK for any K we want it for k equal to infinity but it turns out that if you repeat this for K going high enough you'll see nothing changes anymore you get convergence and you found effectively the version for k equal to infinity what's the complexity in each iteration you do order s squared a computation why is that well you have to do this for every action so that's s then every action out sort of every state so that's s then for every action for restates that's times a let's actually do size of the set as size of the set a and then here you have a sum over all next state says against size of the set s so if order side we set s squared times size of the set of actions is that better or worse than expected max it depends you have a relatively small number of states right then you have all this repetition expected max and this compacts it then you just do the competition for each state once which makes it a lot more efficient this is a theorem that says this will converge the optimal values v star that we were after initially let's take let's look at some intuition of why that might be true actually let's do a quick example then look at the addition I want to get to the final heart I'm going to take your question after lecture let's do an example here v-0 initialize that's 0 v1 what does that mean we have to look for each of these states here's the cool state each of the actions available slow or fast what is the current reward plus gamma times the future reward future rewards are here all zero so we can ignore them the current reward for fast is to the current reward for slow is 1 so 2 is better so fast is going to be our choice and we get our 2 plus 0 and over here we have from the warm state we have fast available which gives you a reward of minus 10 which is bad cool gives you a reward slow gives you water plus 1 so that's better plus 1 here this one is dead it stays 0 now it gets interesting we now have a value for the future state we're now going to compute v2 for this one here we have the action slow in the action fast for slow what do we get we get slow we always stay in cool which means you get a reward for cool for staying there which is 1 plus gamma let's assume gamma is just 1 VK for the next time we land in the cool state so there we have 2 so it's 1 plus 2 then for fast what we get for fast we have a split you could either stay in cool or you could go to warm so it's 0.5 times stay in cool plus 0.5 times you go to warm if you stay in cool you get plus 2 plus you get for the future time if you land in cool you have 2 so it's not a 2 here and he took the action fast no it's still action fast the probability is 0.5 that you move to cool 0.5 you move to warm if you move to warm you can still get 2 for choosing fast and then at the next time you land in warm which gives you 1 so we end up with here is 0.5 times 4 plus 0.5 times 3 which gives us 3.5 this gave us three to the optimal thing to do with two time steps left from the cool state is to take action fast and that is an expected return of three point five that's our value over here we can do the same thing for the other states so you always look at this equation over here computed for all actions and then take the max why does this work out what is the intuition here why does VK converge at some point 4k high enough well let's look at what happens we have low drawing here consider VK and VK plus one just think of this again as expected max threes you don't have to worry about value iteration even just think of it as expected max if you already know very well if you compute VK you cut off you tree right here after K layers and here goes up to k plus one what's the difference you compute values at the bottom and propagate them up so one way to think of the difference here is that this is actually also a tree of depth k plus 1 but in the bottom layer all the rewards are 0 you can use a tree of depth capable Swan with just in the bottom layer or where it's equal to 0 that's the same as using a tree of depth K no difference in the result okay now these trees are on the same kind of depth we can start comparing what happens what happens well you just expect the max all rewards are accumulated up here right you have the same options available the only way things will differ is by what happens at the very end okay so how different could things be at the very end well the best days in that last step you get are max in the worst case you would get our min which is the minimum of all possible rewards but since we do discounting you actually don't countess our max or our menu counted as gamma to the K times our Max or gamma to the K times R min so the maximum difference you can get between these two commutations the value at the top will differ by at most gamma to the K times the max of the absolute value of the reward overall state action state triples so if K is large enough gamma to the K will be really small and so what you find out is that for deep enough tree that is for a valuation that runs in of iterations bringing an extra iteration makes a really small difference and in the limit for K going to infinity that difference goes to 0 because gamma to the K for gamma smaller than 1 will go to 0 and our max is bounded so that's why value iteration will converge that's it for today
Up Next

62:47
PPO Implementation With PyTorch | Reinforcement Learning Tutorial
@MachineLearningwithPhil
85.7K views•2020-12-24

73:14
3D Computer Vision: Lecture 1 Part 2 - Projective Geometry
@cvrplabatnus8618
15.3K views•2021-01-20

13:03
Bypassing Tor Censorship: Bridges and Pluggable Transport Guide
@Coding_ForEveryone
397 views•2024-06-11

18:41
Neural Networks Explained: Math, Layers, and Learning Fundamentals
@3blue1brown
21.9M views•2017-10-05
Related Study Plans & Knowledge Roadmaps
Structured learning paths in Artificial Intelligence
artificial-intelligence
PINNs: Fluid Dynamics with PyTorch & DeepXDE
01Calculus & Fluid Dynamics Foundations
02Deep Learning & PyTorch Basics
03Introduction to Physics-Informed Neural Networks (PINNs)
+ 3 more learning modules
32h6 modules
Explore Roadmap
artificial-intelligence
Aligning LLMs: DPO, TRL & Custom Datasets
01Foundations of Python & Machine Learning
02Transformers and Large Language Models (LLMs)
03Aligning LLMs: SFT and RLHF
+ 3 more learning modules
24h6 modules
Explore Roadmap
artificial-intelligence
Federated Learning: PyTorch, Flower & Privacy
01Python & Machine Learning Foundations
02Deep Learning Basics with PyTorch
03Introduction to Federated Learning
+ 2 more learning modules
35h5 modules
Explore Roadmap
artificial-intelligence
Securing LLMs: Guardrails AI & NeMo Gateway
01Introduction to LLMs, Python, and APIs
02Understanding LLM Vulnerabilities & Threats
03Defending LLMs with Guardrails AI
+ 2 more learning modules
15h5 modules
Explore Roadmap