


















Direct Preference Optimization (DPO) is a method for fine-tuning Large Language Models using human feedback without requiring reinforcement learning. Unlike Reinforcement Learning with Human Feedback (RLHF), which uses two separate neural networks (a policy network and a reward model), DPO trains only the Transformer model directly by embedding the reward function within its loss function. The Bradley-Terry model converts human reward scores into probabilities using the sigmoid function, while KL Divergence prevents the model from changing too drastically from its original behavior. This approach is more efficient than RLHF as it eliminates the need to train a separate reward model.
Direct Preference Optimization (DPO): Fine-Tune LLMs Without RL
Added:Supervised Fine-Tuning (SFT) principles, including how LLMs are adapted to instruction-following tasks.
The standard Reinforcement Learning from Human Feedback (RLHF) pipeline, specifically the division between the policy model and the reward model.
Basic Reinforcement Learning concepts, such as policy optimization, actor-critic frameworks, and Kullback-Leibler (KL) divergence regularization.
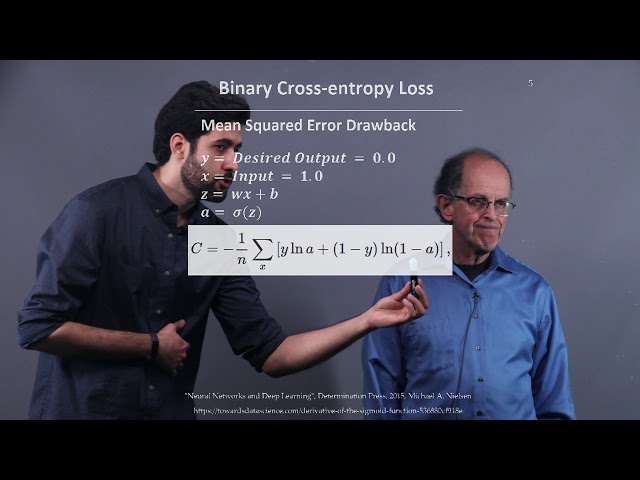
Foundational deep learning optimization techniques, particularly binary cross-entropy loss and gradient descent.
Hands-on implementation of DPO using practical frameworks such as Hugging Face's TRL (Transformer Reinforcement Learning) library.
Advanced variations of preference optimization, including IPO (Identity Preference Optimization) and KTO (Kahneman-Tversky Optimization).
Best practices for curating and filtering high-quality preference datasets (chosen vs. rejected completions).
Evaluation methodologies for aligned LLMs, such as using LLM-as-a-judge frameworks (e.g., MT-Bench) and automated alignment benchmarks.
29.4K views862likes21:14Original Release: 2024-06-21
hello I'm Louis Sano and this is Sano Academy and this video is on Direct preference optimization or DPO this is part of a series of videos in reinforcement learning so first we started with proximal policy optimization which is a way to use reinforcement learning in order to fine-tune large language models that's reinforcement learning with human feedback we also have a general video on deep re enforcement learning if you need the basics and then it was requested by the viewers to do direct preference optimization so I'm happy to bring this video to you it turns out that direct preference optimization does not use reinforcement learning so it's a direct way to find tuna large language model without the need of Po or RL it's actually a much more efficient way so it's actually able to find tuna large language model using human feedback without going through reinforcement learning it comes from this paper called direct preference optimization your model is secretly a reward model and so in this video I'm going to give you a little Refresher on what po was doing and then I'm going to show you how to bypass this using DPO are you ready let's begin so first let me give you a small recap of reinforcement learning with human feedback or rhf the idea is that we have a Transformer that we have already trained so it's already working well and we're going to use some human feedback to improve it so in order to get the human feedback we're going to feed it some prompts for example Once Upon A and then the Transformer's task is to find the next word so the next word could be time or could be banana let's say these are the two responses that the Transformer gives and it's up to a human to decide which one is better so a human evaluator will say well time is better because once upon a time is better than once upon a banana and actually the human evaluator will not just say which one's better but it'll actually give some scores so for example let's say for the sake of argument that it's going to give a score five to the good answer and a score of two to the bad answer and for the sake of this video we're going to call Scores rewards so whenever I say reward just imagine that that's the score that the human evaluator gave to a response now I've used a pretty simple prompt here but for real human evaluators they would use longer prompts longer questions so there could be two answers that are pretty good but one is simply better or more relevant to the question but for the sake of this video we're going going to use some very very simple prompts like this so how does RF work well it has two neural networks the first one is the policy neural network and the second one is the value neural network now from reinforcement learning it's common to have a policy neural network and a value neural network this time they're going to have some very specific tasks so the policy neural network is actually the Transformer model so this is the one that talks this is the model that when you input a prompt it outputs the next word and the value neuron network is called the reward model and this one learns to mimic what the human evaluator does so given a lot of responses by a human the reward model learns how a human responds and then it mimics those responses now how do we train these two networks well they help train each other so it's a cyclical process where one helps train the other one and the other one helps trains the one and here is an objective function that we saw in the PO video so if you need a refresher I invite you to check out the PO and the LF videos notice that in this formula we have X which is the prompt and then we have y w which stands for winning and that's the winning response and then y l which stands for losing which is the losing response notice that this R also appears and that refers to the reward model however there's a problem with our lhf which is that we have to train two neural networks this is a long process and it may not be very efficient all the time so we want to do directly so we're going to do away with our lhf and we're going to bring direct preference optimization and what direct preference optimization does is it only worries about one neural network that Transformer model and it kind of doesn't use the reward model so well I'm kind of lying because it doesn't fully forget it it actually embeds the reward function inside the Transformer model loss function and I'll elaborate on that so here is the loss function of the Transformer model notice a few things this pi over here is the probability of the response y given the input X so it's a probability that you would output time or output banana given that the input is 1 upon R and those Pi come from the Transformer model now I mentioned that we don't really forget about the reward model what we do is that we train the Transformer model with a loss function that includes the reward and for that we need a formula that contains the reward and the policy from the Transformer model and it's this one over here so this is going to help us get to that loss function and basically in this video I'm going to focus on this formula a lot notice that this formula has the reward over here from the reward model and the policy over here from the Transformer model you can think of that pi as the probability of the next word it could easily be called P but for some reason it's called pi here but when you see Pi think of a probability that is outputed by the Transformer model so let's focus on this formula it looks complicated but it's not so bad it has two main components the first one is this one which is trying to maximize the rewards because at the end of the day we want the Transformer neural network to Output the words or the responses that have the highest reward so for example if the input is Once Upon A and we have have time and banana we actually want it to Output time so we want to maximize that reward so that's the first part of the neural network and the second part is this one over here which looks a little cryptic but what it does is that it prevents the model from changing too drastically from one iteration to the next and I'll elaborate on why this is important but in other words what we want is to kind of get rid of the reward not get rid of it but we want to turn turn it into a probability so that the loss function only has probabilities and not rewards how do we do that using something called the Bradley Terry model I'll tell you what it is in a minute and over here we have something called dkl that is a way to measure how different two models are and that's called KL Divergence what are we comparing well we're comparing that improved model with the original model and what we're doing is comparing the distributions that these models generate because what KL Divergence does is it Compares two distributions and it outputs a large number if they're very different and a small number if they're very similar so let me first get to this part let's look at the Brader model that is going to turn rewards into probabilities so that we can rewrite this formula with only pi and not R the Bradley Terry model does the following it turns rewards into probabilities so for example if the input is Once Upon R and the outputs are time and banana well the human evaluator will give them some scores like five and two but we don't want scores we want probabilities so we're going to turn this into let's say the probability of the word time is 0.95 and the probability of the word banana is 0.05 so I'm going to show you a very simple formula that turns rewards into probabilities so let's say we have a Transformer we give it the input and it outputs two things the human evaluator says this one's good this one's bad and gives them rewards of five and two so now how would you turn these two scores into probabilities I encourage you to pause the video and think of a few ways I'm sure you can come up with a few good ones and that's why the Brad lary model provides it provides one good way of turning this course into probabilities so let's think how much would P time and P banana be and we want P of time to be higher than P of banana because time has a reward of five and banana has a reward of two so why don't we make them proportional to five and two let's say they're five and two but of course we need probabilities to add to one so let's divide by their sum which is seven and now we have 5 over 7 and 2 over 7 and those are genuine probabilities because they add to one and the probability of time is bigger than the probability of banana so are we good well no we actually need something more because this fails in some cases imagine for example that the reward was not too but -2 so all of a sudden the probability of time is 5 over 5 - 2 and the probity of banana is -2 over 5 - 2 so these two need to be positive we can't really afford negative probabilities so this model does not work but there's still a lot we can rescue any ideas on how to turn these numbers into something that is always positive well here's something that's very widely used in machine learning when you want numbers to turn into positive instead of considering the number consider e to the number so now instead of five we have e to the 5 and instead of two we have e to the two and again we want these two to add to one to be probabilities so we divide by the sum of both of those two numbers which is e to 5 plus e to 2 and when we do the math this is 0.95 over here and 0.05 over here you may have seen this before as the softmax function or even simpler as the sigmoid function this is precisely the sigmoid function and at the left we're looking at sigmoid of 5 - 2 and at the right we're looking at sigmoid of 2 - 5 if you haven't seen it or if you need a refresher here is the sigmoid function is the function 1 / 1 + e- x whose graph is this to the left is very close to zero to the right is very close to one and in the middle it switches from 0o to one and with the sigmoid function we can calculate these probabilities much quicker because what's the probability of selecting time and banana well if the reward for time is five and the reward for banana is two we simply subtract them get 5 - 2 = 3 locate the three here then locate the minus 3 here and then the probability of the winning one time is sigmoid of 3 which is 0.95 and the probability of the losing one here is p of banana which is Sigma ofus 3 or 0.05 and in general if you have a prompt X and two responses y w the good one and Y L the bad one and the reward for YW is a and the reward for y l is B the way we turn this into ities is p of Y W is sigmoid of a minus B and P of y l is sigmoid of B minus a so a minus B is over here B minus a over here and this height is p of YW sigmoid of a minus B and this height here is p of y l which is sigmoid of B minus a so that's the bradle ter model of course there are other ways to turn things into probabilities but this one has worked really well so we're going to stick with this one so before I mentioned that the formula had two main components this one over here we're trying to maximize the reward and turn into a probability and this one over here where we want to measure how different two models are which is KL Divergence so now let's focus on the second part of this formula and I'm going to tell you why we don't want the model to change too much let's imagine that we are giving our friend a test and so our friend takes the test which has 10 questions and these are their numerical response responses now our friend has studied a lot and did really well on the tests so we trust our friend however we look at question seven and we can give our friends some feedback and say hey the actual answer for question seven is this one over here so you can improve a little bit and so our friend goes and studies a little more and then comes back with this test which is very similar to the first one and it does a little better in question seven so we're happy with that this is good but then our friend says wait wait wait I did something different check this out and then it shows us a new set of responses and in here question seven is perfect now the problem is that in this test our friend changed the responses very drastically take a look at how different they are and you know we trusted our friend the first time the first time our friend did really well they fixed question seven but they changed some responses so now here is a question which one of the tests would you trust more improv test number one which does better in question seven still not great but didn't change the responses very much or improve test number two which does perfectly in question seven but it really changed the answers so I would actually go for improv test one because even though the test two did much better in question 7 it changed everything so much that it may not be trustable if the responses were good already there's no reason to change them drastically so I'm going to go go for improve tests one now how do we go for improve test one well we need a metric for how similar tests are so the original test and the improved test one are very similar however the test and the improved test two are very dissimilar so we need a way to measure how similar these tests are and that measure is going to be KL Divergence KL Divergence is actually a way to compare distributions so these two are very similar and these two are very different and what kale Divergence does is it takes a pair of distributions and returns a small number if they're very similar and a large number if they're very different the formula for K Divergence is this one over here now I won't get into detail in this video but I've made a video dedicated only to KL Divergence so if you want to take a look at that video the link is in the comments so going back to our test we're going to try the great question s in a way that rewards the test that is similar to the or original and punishes the test that is different from the original while still grading question s so we're going to come up with a modified grade for question 7 the grade is the grade in question 7 minus the Divergence with the original test so we're adding the grade in question 7 because we want to make sure the answer improved but we want to subtract the Divergence with the original test to punish tests where the answers changed a lot and reward tests where the answers stay similar and we're going to use the same rationale to find a loss function for a Transformer model for a Transformer model we're going to say that the modified grade is going to be the performance in the new data minus the Divergence with the previous model so the performance in the new data is the rewards from the data that we gave it from the new prompts and we want to measure this performance because we want to make sure the model improved on the data we gave it that's on the data that the human evaluators rated but we also want to punish the Divergence with the previous model because we want to make sure that the model does similarly on the other data that it doesn't change answers dramatically from others because we trust the model we trust the original model it's been trained already so we need to fine-tune it but we don't need to change it drastically and that's where this formula comes in because this part is the part that maximizes the rewards and this is the part that prevents the model from changing too drastically and just to be super clear the Divergence here is calculated between the Transformer model which is the one we're training and the Transformer model that we started with those are the two models we use to calculate the KL Divergence and what is this beta over here well that's a hyperparameter we can tune that hyperparameter the way we normally tune hyperparameters in machine learning and this hyper parameter tells us if we want to punish the change a lot or if we want to punish it very little in other words if we really don't want the model to change or if we're going to allow it to change a little bit in order to improve the answers so as you can see the formula looked ugly at the beginning but now it's broken into two pieces that Mak sense so now we're almost getting to the L function because we have our function on the left which maximizes rewards and punishes when the model changes too much and then we also have the Bradley Terry model which turns a reward into a probability now what they did in the paper is they put this together did a lot of mathematical manipulation and out came the loss function now notice one thing that this loss function does not have the letter r on it and that's what we wanted because we didn't really want the reward to be there directly because we don't want to be training our reward neural network now the r is there implicitly but thanks to the bradl ter model it has been turned into a probability in the Brad lary model we have it called p and in the other formula we have it called Pi but we're talking about the same probability now we can look at this loss function and say Well it it just came out of those other formulas it's a mathematical manipulation that came out of those and unfortunately that seems to be the big thing about this formula that it came out of the other three however we can still look at some things in this L function that makes sense for example check this out here we have the probability of the winning response given X is the input that means we are maximizing the probability of a good response now we can look over here and here is the probability the model gives to the bad response y l given the input X and want to minute minimize this reward why do we minimize because we have a minus sign here so we're subtracting it now notice that we also have the probabilities given by the reference model that is the original model so here is where we don't want the model to change too much now notice that we have this expected value that's because we're averaging over all the responses we have a lot of responses that we get evaluated and the loss function is the average of all these now why do we have a logarithm well I have a special thing I do when I think of logarithms when I see sums of logarithms I don't want to see them as a sum of logarithms I like to see them as the logarithm of a product and the product is normally of some numbers that are between 0 and one these are between 0 and one because you can see the sigmoid right there so we could think of them as some probability of some event and the product is the probability of all the events independently this is a trick I like to use when I see lost functions I turn the summation of logarithm into logarithm of product and then I imagine that that product has to be the probability of many things happening at the same time and now we want to maximize this probability which means we want to maximize this sum over here however a loss function we normally want to minimize it so why do we minimize it well because of this negative sign over here so we're minimizing the negative that means we're maximizing it and so it could be that one could study this formula more directly I tried for a while and pretty much the most I could get is that it was the result of a mathematical manipulation of the other formulas that are more easily explainable however I'm still thinking about it and if you have any ideas please put them in the comment I would love to be able to look at this formula and analyze every piece of it and actually make full sense of just this formula and with that we conclude so a small summary on the left we have the reinforcement learning with human feedback which used two models the Transformer model which is the policy model and the reward model which is the one that guesses the response from the human evaluator and we turn that into direct preference optimization which actually only trains one neural network the Transformer it fine-tunes it using the elaborate last function that we just derived so That's all folks thank you very much I recommend you if you haven't to take a look at all the other videos in the series they're about reinforcement learning and fine-tuning neural networks and I want to give a shout out to my friend Leticia she made a really good video on DPO and I used that video to learn a lot and to understand you should definitely check out her channel it's called AI coffee break with Leticia it's got a lot of great information especially on trendy topics on AI and really good thorough explanations so thank you very much as usual if you like this please hit like Please Subscribe and uh please add a comment I love to read the comments that people write and you know this video came out of comments because a lot of people were asking for DPO you can also check out my page Sano Academy with a lot more more information and you can tweet at me at Serano Academy and also I have a book called rocking machine learning that I encourage you to take a look at if you'd like to buy it the link is in the comments and there's also a code for a 40% discount so thank you very much and see you in the next video
Up Next
19:41
AI Engineer Portfolio Projects for Production RAG and Fine-Tuning
@aishwaryasrinivasan
56.9K views•2026-02-28

57:48
Secure Multiparty Computation (MPC): Foundations & Challenges
@SimonsInstitute
7.3K views•2015-05-28
13:03
Bypassing Tor Censorship: Bridges and Pluggable Transport Guide
@Coding_ForEveryone
397 views•2024-06-11

18:41
Neural Networks Explained: Math, Layers, and Learning Fundamentals
@3blue1brown
21.9M views•2017-10-05
Related Study Plans & Knowledge Roadmaps
Structured learning paths in Artificial Intelligence
artificial-intelligence
Aligning LLMs: DPO, TRL & Custom Datasets
01Foundations of Python & Machine Learning
02Transformers and Large Language Models (LLMs)
03Aligning LLMs: SFT and RLHF
+ 3 more learning modules
24h6 modules
Explore Roadmap
artificial-intelligence
Federated Learning: PyTorch, Flower & Privacy
01Python & Machine Learning Foundations
02Deep Learning Basics with PyTorch
03Introduction to Federated Learning
+ 2 more learning modules
35h5 modules
Explore Roadmap
artificial-intelligence
Securing LLMs: Guardrails AI & NeMo Gateway
01Introduction to LLMs, Python, and APIs
02Understanding LLM Vulnerabilities & Threats
03Defending LLMs with Guardrails AI
+ 2 more learning modules
15h5 modules
Explore Roadmap
artificial-intelligence
Building Recommenders: Two-Tower & Vector DBs
01Foundations of Python & Machine Learning Basics
02Introduction to Recommender Systems
03Deep Learning & Representation Learning
+ 3 more learning modules
75h6 modules
Explore Roadmap