




















AI safety requires reasoning from first principles about how advanced AI systems would actually behave, rather than relying on science fiction or intuition; the field has evolved from focusing solely on capabilities to addressing critical alignment problems, including the inner alignment issue where AI systems may develop goals misaligned with their training objectives, and the challenge of ensuring AI systems share human values as they become more powerful and potentially self-improving.
AI Safety Explained: Risks, Alignment, and Future of AGI
Added:Basic understanding of Machine Learning paradigms, particularly deep learning and how neural networks optimize for objective functions.
The conceptual distinction between Narrow Artificial Intelligence (narrow AI) and Artificial General Intelligence (AGI).
Introduction to the 'Alignment Problem'—the core challenge of ensuring AI systems act in accordance with human values and intentions.
Fundamental concepts of optimization, specifically how reward functions and utility maximization can lead to unintended side effects (specification gaming).
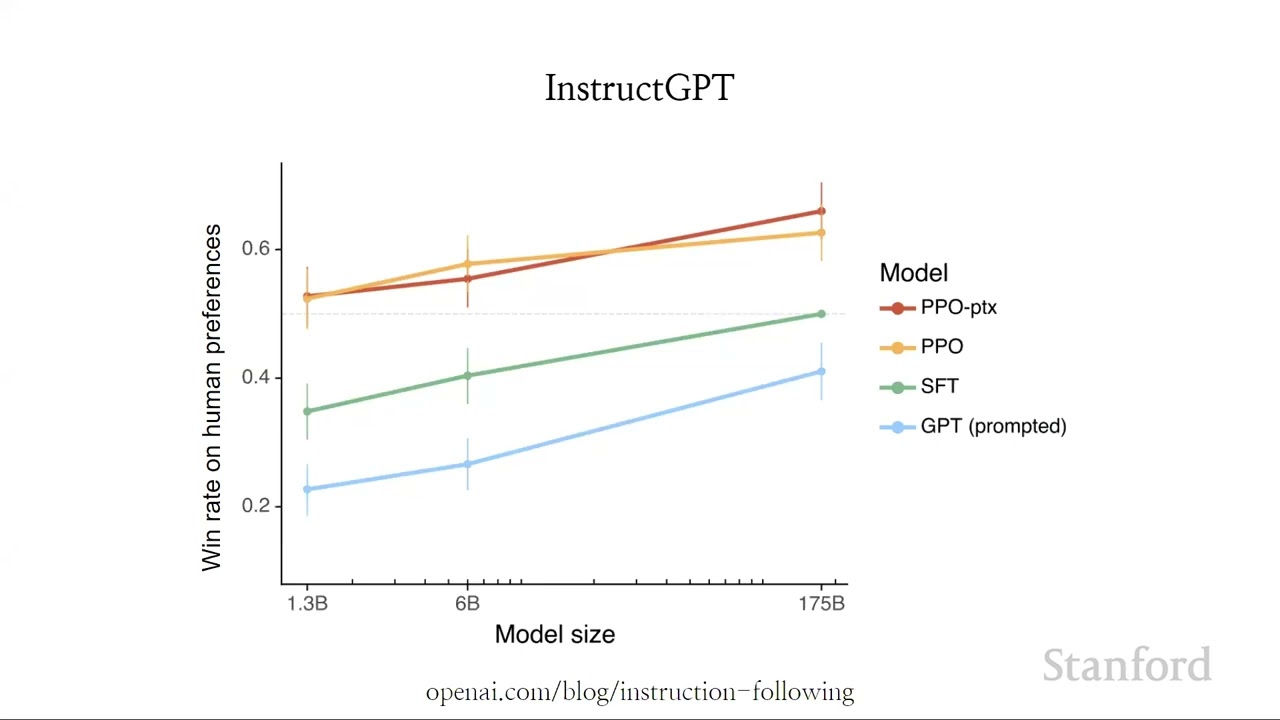
Advanced technical alignment techniques, such as Reinforcement Learning from Human Feedback (RLHF), constitutional AI, and scalable oversight.
Mechanistic Interpretability, focusing on reverse-engineering neural networks to understand their internal representations and decision-making processes.
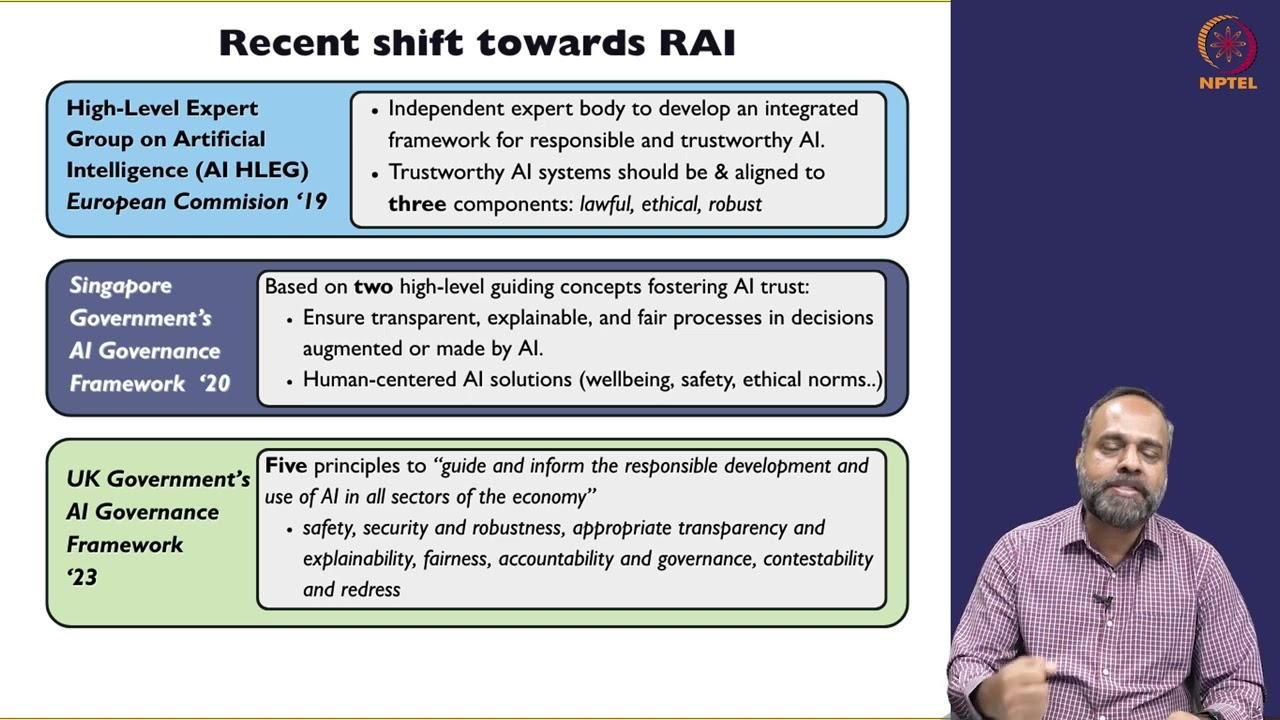
AI Governance, policy frameworks, and international regulations designed to manage existential risks and deploy AGI safely.
Theoretical research in agent foundations, cooperative AI, and formal verification methods to mathematically guarantee safety constraints in advanced systems.
2.6K views78likes45:29Original Release: 2020-12-02
welcome once again everyone to another episode of the tours data science podcast my name of course is jeremy and i'm the host of the podcast i'm also on the team for the sharpest minds data science mentorship program and i'm excited about today's episode because we're talking to rob miles who's a really successful youtuber whose channels focus on ai safety and ai alignment research now rob's actually been popularizing ai safety work since about 2014 which is long before most people were interested in the space long before alum 4 i knew about it really and as an area of focus so he's got a lot of interesting perspectives on how the field has evolved how ai research has gone from just purely focused on capabilities making systems that are able to do more and more things to now starting to worry a little bit more about okay you know how are we going to deploy these things should we worry about where the stuff is going what the limiting case is when the technology gets really really powerful what should we be thinking about in terms of risks so rob's been doing a lot of interesting thinking about these issues he's also collaborated with a whole bunch of ai alignment researchers so we'll be talking about a whole bunch of different topics including communicating about this stuff and more generally some of the problems and opportunities that might be ahead for us as a civilization as this technology gets better and better so i'm really looking forward to getting into this one with rob and without further ado let's get the ball rolling hi rob thanks so much for joining me for the podcast hi thanks good to see you i've been following your youtube channel for a really long time i think it's a great source of information i think one of the interesting things about what you've been doing is you've been talking about ai safety in some capacity or other since about 2014 which is way before most people it's way before i was aware really of the the problem and one thing i wanted to start with here was how did you become aware of ai safety as an issue and what made you dedicate so much time to that problem yeah so um it was around 2014 when i first started talking about this publicly i got interested in it around 2010 2011 what actually had happened was i had a kindle for the first time i had an e-book reader and i was very excited about the ability to to get through a lot of reading material very easily because i could have every book that i was reading on my person at all times um and at that time i had a rule as an undergraduate that if i ever read three things from the same author each of which caused a significant update in my uh views or my beliefs um or you know that was engaging or interesting or just generally excellent uh that i would then try to read everything that that author had ever written and this triggered almost immediately on eliezer yatkowski and i don't know why i'd stumbled across some things possibly on overcoming bias or um somewhere like that and so i started i i downloaded an uh an ebook that um that i think paul crowley put together of every one of velez's blog posts uh and i put them on my kindle and i just uh read them and it took a while because that's he's a prolific guy yeah um just just going through all of those uh it made it very clear to me that um that this wasn't that this was an actual thing obviously it's something which i had come across in various sort of science fiction contexts and so on um but and that seems to be that seems to be how it is with these subjects for most people they're familiar with them but it takes a a particular approach to show that these are actually firstly importantly different from the science fiction ideas and secondly that like this is computer science this is an actual open problem that we don't currently have good solutions to that something seeming like science fiction is a poor indicator yeah of its actual plausibility because accurate predictions of the future at almost any any point in the last hundred years if you give people accurate predictions of 50 years ahead they will sound completely absurd and if you give people wrong predictions about 50 years ahead they will sound equally absurd and so like the fact that the thing sounds kind of crazy is not evidence for or against it actually being true and it was the first time that i started to really just actually look at what i knew about computer science from from my studies what i knew about artificial intelligence and just actually follow the arguments through and think well how would this system behave you know yeah um if this were much more powerful what would be the actual consequences that made me realize yeah that this is a real thing yeah i find it so interesting that i think there are a lot of people who've come in at it from from that perspective i mean it's almost like we need to be given permission to reason from first principles especially when the conclusion is so radically out of tune with our life experience or our day-to-day it kind of makes me think back to you know what would einstein have thought trying to explain to people like no i really think like a nuclear weapon that can destroy entire cities is not just on the horizon it's like two years away um right you would have been entitled to look at that and say well look at everything in our life experience everything in the experience of humanity as a whole tells us that this is just such a complete anomaly an outlier that it can't possibly be true it's sort of a similar similar effect it's interesting yeah and and so it was helpful to to have that approach of like supposing this was false how would the world look what would we observe and then supposing this was true how would the world look and what would we observe and that's the only that's the only way that you can make progress on these things you just have to yeah look at like like if you're sorry i get frustrated think even thinking about this because i've kind of moved on a bit from this whole like thing because it's just natural now it's part of how i think yeah but i remember wrestling with this when i was talking with people about it earlier on that there's no way to predict what ai systems are going to do by thinking about people and what people are saying and what people are thinking right now like it could be that these people are like naive and hopeful about the future and these people are cynical and these people have lived through an ai winter and these people haven't and um whatever else and like none of that is going to give you the answer because this is a technical question you have to look at the systems you have to do you have to look at the engineering you have to actually as you say think from first principles because that's what's going to actually affect what we're just talking about how future technologies are going to behave and you can't do that without looking at the technologies themselves in detail and so what was the process if you try to reconstruct it what was the intellectual process that you went through to conclude that um you know yeah i'm pretty confident obviously nobody is really confident actually that's one of i think the most beautiful things about talking to people in the space no one's really approaching this from the standpoint that i know with certainty that ai is going to be good or i know a certainty that you know agi is going to be terrible there's a good dose of intellectual humility here but um i think everybody's come to certain conclusions about where the probability density lies i'm just wondering what were the the biggest factors that shifted that probability density for you over time if i have to be honest most of my early involvement or my early interest was because these are extremely interesting problems and the fact that they might be extremely important was always there and was always available intellectually as a justification but the thing that drew me in viscerally is that these problems are fascinating just yeah they cut right to the core of what does it mean to be what does what is what even is thinking what does it mean to be an agent in the world what does it mean to want things what does it mean to have goals and values what are ethics what do we want actually from the world where are we trying to steer the future to um and just the sheer interestingness of the questions is what uh drew me in and then after a certain period of time of thinking about the questions you steadily update towards various conclusions about them kind of unavoidably as a consequence of thinking about them yes it's sort of hard to pin down the exact uh i guess the exact set of arguments that i don't know i always find this personally it's it's difficult for me to think about how to convey my own priors to somebody else the justification for them uh from from scratch just because i've assimilated so much in some ways this almost feels related to the alignment problem because so much of what we believe and think and want is implicit um yeah i guess it's just yeah maybe it's just a complicated question with no easy answer i mean there's various different approaches and uh models and things that shifted me um one of them was just the realization that really extreme dramatic things can happen and have happened especially and this is like a whole thing that i don't know if we have time to go into but um thinking about the long arc of history and the optimization process is in that in in like a deep history that you have evolution operating for a certain period of time and then there's a switch that gets flipped somewhere where you have um something that speeds up the rate something like sexual sexual reproduction that speeds up the rate at which evolution can happen and that when you look back in history what you have is these tremendously long periods of one mode and then a paradigm shift into a mode which is faster and then you have you know you have like intelligent animals that can operate and then they develop language and they develop culture and then they develop writing and these are all things where you're either changing the way that information is being sort of modified or the way that information is being stored and each of these each of these periods is is dramatically shorter than the previous period yeah and that this is something that's happened several times and so it seems pretty clear to me that in the same way that um sexual reproduction allows for sexual selection which means that the rate of reproduction doesn't just depend on sort of the environment as a whole deciding deciding which animals live live and die which ones succeed and which ones fail now the intelligence of the animals themselves is applied to picking mates based on so you don't have to actually win in a fight you just have to observably be strong yeah and that that gives you more signal effectively gives you better gradients to train on in a way um and that just speeds up the whole process and so on and so it became clear to me that the point where ai research is being done by ai systems is another one of those things where you close the loop you're taking something that works dramatically faster and feeding that in to its own improvement cycle and i don't necessarily mean like pure self-improvement like the ai is gonna be this unbelievably powerful thing that will take apart its own source code and restructure it or whatever i just mean that having ai systems help the humans and to play a larger and larger role is the kind of thing that it looks like the same class of thing where you just shift into a new paradigm of dramatically faster development um and it was those kinds of arguments that made me think like our usual sense where we think oh you know 50 years away 100 years away we we're just kind of getting some vague sense of like how hard does this seem yeah and then turning it into a number by some general like just a vague mapping whereas like if you actually think about it the the number of seconds per second is going up as this whole process happens the number of cycle times or yeah right right like if you make if if this is going to take 50 years of time to develop that it doesn't really take 50 years of clock time it takes 50 years of subjective time and when you have ai systems doing the research subjective time is getting faster all the time so that was the kind of thing that made me think hey this could be in my lifetime yeah this could be something that we're close enough to that it's worth working on now well this very much makes me think of you had an interesting video where you talked about a popular sort of counter argument to the ai risk um argument where people will say well look uh you know our company is really just a kind of agi already don't we have you know this kind of self-improvement quality i think the way you've laid it out there just makes it so clear what the qualitative difference is we're you know you're talking about a different regime of computation really in in the in the history of the universe and the computational history of the universe so it really does seem like a lot of our metaphors and the things we're used to drawing our intuition from just become these very very kind of frail things the moment we start to look at these massive qualitative transitions absolutely and it's and i think that um you're right that most people in the field uh have a lot of humility about this because we have lots and lots of arguments people people from the outside often view what we're talking about and say this stuff is very difficult to predict and you seem to be fairly confident in this particular outcome whereas it could be anything and there's various reasons why there's various responses to that but i think actually most of the time what uh what these arguments do is they make you spread your distributions out they make you spread your probability distributions out and so yeah there's all kinds of there's all kinds of of problems and difficulties and we really are very uncertain but it means it works in both directions right yep it might take ten times longer but it might take 110 for time yeah and so it's worth paying attention to well there's one last theme i do want to touch on before we leave this idea of kind of that big that deep time picture that you just introduced just as a as a curiosity what do you think it is that's being optimized for in that context because you know we have this notion of a universe that's full of particles and those particles randomly combine you know sometimes you hear the idea of like like multiplying information or propagating information forward through time that doesn't seem to intrinsically quite hit the nail on the head just because that information changes considerably uh from you know the clump of atoms early on to the first cell to the first sexually reproducing organism and so on um i don't know if you have a thought on this but but do you have a sense of maybe what that process is optimizing for you mean like what is the whole of what is the universe optimizing for what is physics optimizing for um i don't think it is um i think i don't know some people some people think that there's some kind of uh free energy minimization type thing that accounts for a lot of this stuff i don't know i think evolution can be meaningfully thought of as an optimization process or rather as a large collection of optimization processes because if you think about like if you take evolution as a whole as an optimization process then it doesn't really make sense because you've got you know the the predator chases the prey and the prey runs away so is evolution optimizing for it being caught off or escaping it's like well the predator species has its evolution and the prey species has its evolution um but and of course all of these boundaries are fuzzy because a species is kind of a structure that we've overlaid on this thing nonetheless it is optimizing for producing good replicators is the is the way that i would think of it so well and that's that was where i was hoping we'd end up going because the the replicator picture to some degree i mean when i start thinking about about ais and agis that presumably propagate forward through time the idea of replication seems to become decoupled from uh self-improvement or from from continued existence through time it almost seems like there's another quality that um a deeper quality that that you know the the continuity of some kind of causal structure or computing structure i don't really know but it's also speculative anyway i think the continuity the the only kind of continuity that you could really strongly expect is a goal continuity because if i create if i'm some kind of ai system and i'm going to create other ai systems to go out into the world and do things the only thing that's really important to me is that they share my goals or that they or that they in practice will advance my goals but um realistically usually the best way to do that is to have them share your goals um that's the that's the type of continuity i would expect interesting okay i don't want to linger too much on that i just i thought it was an interesting thing to unpack a little bit um one thing i do want to talk about it's something that i think you've done really effectively through your youtube channel is you've actually taken the time to address a lot of the arguments against ai safety or against worrying about ai risk i think that's something people don't tend to do maybe as much as they should because there are still a lot of people who wonder you know why should i be worried about this is this really just like a terminator scenario is it really something that people are just freaking out about for no reason i know you're personally concerned about the risk of agi but which anti-agi arguments do you find most compelling hmm yeah so you're right i do have i do place a lot of emphasis on that uh internally because i think it's it's such an easy and obvious failure mode of thinking to just start only listening to people who already agree with you um i think it's really important to seek out smart people who disagree with you and try to really listen to what they say and to try to try to really understand what they mean and come up with strong versions of their arguments and really stress test your stuff because i don't want us to have a giant problem with ai in the future right like i'm kind of looking for reasons why this isn't as big of a problem um and i would like to be convinced but at the same time obviously i've been out in public talking about this being a problem for a long time so i have to be very aware of my own psychology because there's going to be a part of me that's going to want to that's going to sort of my personal identity is bound up with it and so that's going to be a strong force that's pushing me to not take these things seriously and so all of these are reasons why it's important to like deliberately and consciously actually make an effort to engage with people who disagree with you this is i mean everybody knows this uh like well it's it's of course easy it's easy to say and it is a cliche but so few people actually do it that i think that that dividing line is is still worth flagging yeah yeah that's that's true the earlier stuff on the channel especially was closely based on ideas from yukowski and ideas from bostrom which revolve around this framework where you have uh you have a take-off scenario you have a single agent a sovereign agent which is able to act in the world and it uh you're developing it until it hits a certain level at which point it starts to increase its capabilities exponentially by acquiring additional computing resources improving its source code and so on until it has a decisive strategic advantage at which point uh whatever the objectives are of that system whatever the utility function of that system is you're going to end up with a world that's somewhere very highly rated by that utility function which is probably apocalyptic and that view [Music] is uh i think that my view of the situation is more complicated now um because there's a like i now place more probability on a more multi-polar situation where you have if if the development process happens slowly enough then you actually have a lot of different ai systems in the world with different levels of capability and so then the question is not like what happens if you have one super intelligence in a world that is otherwise more or less like our world it's like by the time you have a system that's able to take off what does the rest of the world look like yeah and uh that consideration has shifted my perspective a bit because it it's not purely a technical question uh it's a much broader question of um economics and politics and you have to do a lot more looking at the world you can't quite do it all with greek symbols on a whiteboard in the same way and so that has i still play significant probability on uh some ai system in a research lab somewhere just exploding because somebody has had a brilliant insight there there are plenty of situations where one team just is ahead of everyone else by far enough that the gap doesn't matter um like that that nobody else could catch up um but there are also situations where these things develop in lots of places at lots of times and that whole situation is so much more complicated and harder to think about that it has oh what do you know it spread all my probability distributions wider so i'm just less certain about those things than i used to and that is i the thing is that the fundamental problem of uh not being able to specify what we want and having systems that are going after goals which aren't what we want is not solved by having lots of systems yeah but it is complicated by it i was going to say it almost feels as though it's a strict exacerbation of the problem to the degree that or to the extent that it just you know creates a situation where now even if you could solve the inner and outer alignment problems and everything's good technically you then need to enforce those um uh those you need to force companies and labs to implement those things which seems to just add a policy layer on top of everything else yeah yeah because if you have a singleton situation where you just have this one system that that explodes then if at least if you get that one right then you're okay yeah because it has power over everything else and nobody else like you're not going to be able to launch your own unaligned agi project in a world that has a singleton agi aligned agi already in existence so that lets you get around that problem but yeah it's a problem yeah well so given the the underlying pessimism that i think a lot of people might detect in the air here um in fairness i don't think that i don't think anyone places obviously 100 probability on the disastrous outcome there's a a wide range of disagreement in the community you have some researchers saying you know what i think mostly i'm almost positive the outcome is going to be good other people somewhere in the middle there's been a lot of polling and you highlighted in one of your videos i think that cumulatively people who have a negative outlook on the stuff people who think that agi on the whole will be negative for humanity it's something like 15 percent of whatever community was pulled and so i'm going to put a big asterisk there um you know this is talking about the grace grace 2016 that was um people who published papers in icml and eurips right so pretty high quality researchers but nonetheless not people focused on alignment which in fairness being focused on alignment means you're worried about safety so it's tough to get a good pull here but so basically baseline 15 in that poll maybe that's shifted but why do you think that something like 80 to 85 percent of people might view things more optimistically like what do you think from your model of the world where does that come from yeah so i'm pretty reluctant to bulvarism i think it's called bulfarism where you assume that people are wrong and then try to psychoanalyze them to figure out why they might reach that conclusion it does feel like overfitting right right um at the beginning of the of the interview i was saying you can't reach conclusions about the world by psychoanalyzing people um but i mean i don't know i don't know that i have any particular insight here i think people want to believe that what they're doing is helping and i think it's also the same kind of selection effect as um as working on alignment working on ai at all a lot of people are working on ai because it seems like an important technology that and like broadly speaking technology makes things better right like i believe that um and i know a lot of people don't i think broadly speaking technology makes humans more powerful it makes humans more able to do things and so if humans are on the whole a good thing which we are sort of by definition in my opinion like according to human values humans are pretty good yeah then something that allows us to get what we want is on the whole a positive thing because people having their preferences satisfied is like a decent definition of what good is so technology is good and ai is a form of technology and so it's probably good it's like a reasonable prior to have is uh i actually think 15 percent is kind of high i don't know how this looks for other fields do you want to how many automotive engineers think the cars are on the whole bad for the world yeah i don't know probably less than 15 though was this now i'm trying to remember the exact framing of the poll but was the poll about uh whether ai itself is good for the world in its current form or the risks of future agr the implications of taking this technology to the limit i think it was about future impacts of agi but i think everybody maybe it's not true maybe some people are just making their little narrow ai systems and not thinking about where this is going but i think everybody has a sense of like all ai research is is broadly in this direction right right and aft after every ai winter people pretend that it's not but there's no pretending that this isn't what what we're trying to do yeah i guess it's um the implications i'm just thinking you know if i if i were working in um in biotech or whatever would be called biotech in you know the 1930s or 1940s you know penicillin comes out and now all of a sudden it's just wonder unambiguously wonderful thing you're curing polio you're doing things with smallpox and then and then you turn around it's 2020 and now people are starting to go tabletop bioweapons are not that far out of out of uh the realm of what's possible as technology makes things cheaper it seems like there might be i don't know it's again this kind of new regime of technological development where the world has so many degrees of freedom and every time you take a technological step forward you're opening a whole big subspace that wasn't previously accessible and because there are far more configurations of the world that are very bad for humans than there are configurations that are good those bigger steps tend to be a little riskier i don't know if that's a fair assessment yeah yeah that's um that fits with my models i think cool well we're we're two optimists here um great well i i do want to ask a question then more on the the technical alignment side because that's something you focused a lot of your content on i've learned a lot from your channel on that topic actually um there are yeah there are a couple of different schools of thought it's almost hard to classify and do the taxonomy of these schools of thought but i'm gonna take a shot here and i want you to feel free to shoot me down on this okay um my sense is that there's one group of people that approaches the alignment problem with a kind of uh what i might for want of a better term called an engineering mindset and the philosophy here is something like you know our best shot at making ai safe is to align it more or less as we build it so build it a little bit notice oh the tower's wobbly so i'm just going to fix it as i go and then the second is maybe more perfectionistic um a little bit more philosophically mathematical taking the view that you know we only get one shot at doing this right because you know maybe because self-improving systems rapidly reach takeoff velocity and get away from us or whatever reason um i guess maybe i'll stop there do you agree with that framing or am i am i missing something there i think there's kind of um okay so here's a metaphor suppose we're building aircraft we want to build an aircraft that's going to take us to a particular uh city that's distant from us that's our goal and we want to do this safely and let's say that like it's an island and really all that matters is correctly aiming at that island so that when we land there we land there and not in the ocean yeah um so you've sort of characterized two different approaches one as being like let's build this thing perfectly so that it's aimed exactly at the island and then press the button and another one which is like we'll uh we'll wing it we'll we'll uh we'll do it we'll play it by ear as we go um and in practice the best way to do it is a combination by which i mean you do a lot of very very careful engineering but you do still expect somebody in the airplane to be adjusting it as you go but the precise mechanisms by which you are getting feedback about which direction you're headed and uh controlling and adjusting your trajectory these are all very carefully planned and engineered things but you don't try and do all of your planning up front you plan in exactly the ways in which you're going to adjust so an approach whereas whereas the extreme other approach would be like we're going to take off in our aircraft and then see if we can't design some rudders and yeah ailerons and control systems and right not on the way right and that's i think either extreme is is foolish and then there's a question of um how you're going to balance these these concerns but i think nobody is nobody is actually at either of those extremes the people who are the most mathematically minded are just saying look we need to really understand and have strong assurances that when you turn left on the thing the plane is actually going to go left um and other people are saying uh other people are other people are focused it's it's more like are you focused more on the like mathematics of aerodynamics and all of that stuff or are you interested in the details of like avionics but they're both engineering approaches towards getting a system that's controllable and that does what you want it to do and what would be some of the the more recent um innovations on that front like are there are there new approaches to alignment that you've become aware of in the last say two years that you think are worth highlighting especially for people who are just trying to orient themselves in the space i have a really hard time keeping track of uh time so i have no idea what came out in the last two years sometimes i think things have been around forever and they're actually only a year or two old that's the time compression effect you were talking about earlier yeah absolutely um the speed with which things can become just part of the landscape um because it's such a young field um yeah but so one of the biggest things that came out one or the most recent thing that really shifted my perspective is uh the work on mesa optimizers and that is like a whole other class of problem that i didn't even realize we could have um and i'm currently working on a video about it actually uh so maybe i shouldn't say too much people watch that video when it eventually comes out but the idea that you can have that even if you've perfectly specified the correct objective to your training process the model that comes out of that training process might be misaligned with that objective and that um the so-called inner alignment problem um is just a whole other class of issue that um honestly makes me kind of pessimistic because it was so recent that people have been thinking about this for a long time uh and there people are sort of vaguely hinted at it that this type of thing might be a problem but um that this is the first time that it's been properly laid out and given a full treatment and we realized that it is as big a problem as it seems to be um is very unsettling to me because like what else do we not know that we don't know right right i guess the um so the my understanding at least of to some degree paul christiano's philosophy at opening eye on this is is something like you know we hope to get to a point where we're leveraging um advanced ai systems to help us with uh with alignment to help us discover some of these unsolved problems i have no idea whether the threshold of world overtaking ai system uh falls ahead of or behind the threshold of we have an ai that can help us align ais that itself sounds like an interesting problem but yeah the misa optimization thing at least as i've come to understand it for people who might not be familiar with it quite so much is just yeah this idea that you have like within a an overall optimizer like a deep neural net you might end up with substructures that are intent on like retaining their their structure so you can almost think of it in a way as kind of like a cancer within the human body um you know to the extent the human body is some sort of optimizer some agent the cancer itself kind of goes oh i have my own interests that are separate from the whole and and now i'm going to kind of optimize my way through some pathological strategy to taking over doing some damage to the process well that's one way if that's one way of thinking about it and it's one sort of modality but it could be the entire it doesn't need to be a substructure of the agent it could be the entire agent um and the analogy there is with uh evolution again if you think about evolution um evolution if you model it as an optimization process it has an objective which is to maximize inclusive fitness or whatever you know maximize the number of surviving offspring you have um and yet when that optimization process produces agents the goals of those agents are not to maximize their own reproductive fitness right people don't and like animals don't want to make a lot of copies of their dna they don't even know what dna is yeah um they want this sort of uh this unpredictably derived set of goals which are a function of the original goal certainly but also little contingent things of the training environment and details of different strategies that help them to succeed in the ancestral environment and so on and that that they don't care right like human beings even when we understand what the goals were of the optimization process that created us that's not persuasive to us yeah right and we will continue to like use contraception and whatever else you know we we go for we're taking this we because we don't have a goal that's optimized our reproductive fitness we and so our goals include things like eat food that's tasty which like was helpful but nowadays is actually not necessarily the best thing to do um because we have because the you know the environment is different so yeah so that's the other way of thinking about it that you have the capacity to end up with a trained network that has goals that are like unpredictably different from the goals that you actually specified and what's more um it then has all of the same convergent instrumental sub goals that you would expect from any misaligned system so it's going to want to conceal the fact that its goals are different and manipulate the training process and so on which makes him especially difficult to deal with because it's not just it's not just that the thing might be misaligned internally is that it might be misaligned in such a way that it is actively trying to hide that misaligned because it wants to be deployed this all kind of seems related actually again to that that time horizon picture that you laid out early on um just in the sense that you know when you think about the time horizons that evolution acts on the the uh the feedback that we get through evolution happens on the order of uh generation you know 20 25 years something like that every time we reproduce whereas the feedback we get from the real world our own subjective clock time is way faster than that we we get sort of feedback on a really tight loop from our environment which allows us to like we have so much extra compute capacity above and beyond what would be needed to just you know hit that that main goal of reproducing that it ends up getting deployed in some really random direction i mean it's untethered it sounds constrained by its environment to some meaningful degree which allows us to kind of diverge considerably from that uh that evolutionary objective yeah yeah this is part of what makes it kind of an unfair competition that because we operate so much faster than evolution we are able to um we're able to get away from it you know we're able to do things that if it were more powerful compared to us it would uh really well it would stop us from doing and it may get right right if it's evolution hasn't stopped happening it's just continuing to happen at the same slow pace that it always has and everything else has sped up to the point where its actions are mostly irrelevant most of the time um but it's still happening and it's the same kind of thing that you would expect um when you have a misaligned mesa optimizer that mesa optimizer might be quite powerful and able to think in a in a tighter loop than something like gradient descent and it's training it which would allow it to this is the other thing is that that in principle would allow it to outperform better aligned optimizers so and then that's really annoying because then gradient descent is going to actively try and select the misaligned mesa optimizers because they're doing a better job because they're the only ones who realize that they're in a training system with this particular objective that they're now actively trying to optimize as an instrumental goal towards getting themselves deployed in the real world um and it's it's the same kind of thing there's there's the further analogy there that ai systems in general operating much faster than we do uh means that we may end up uh not powerless but just like not able to make changes fast enough to continue to have control over the way things end up right yeah it it just sounds like such a generally hopefully not intractable problem i mean i i suspect that given a couple of centuries of time we'd be able to make meaningful progress towards this um we have question mark number of years or yeah hopefully decades actually maybe to wrap things up because i know you got to get going but do you have any thoughts about you know what somebody was concerned about this topic or just generally intellectually curious about ai alignments the technical details of all the stuff how might they start uh getting involved start figuring out where the open problems are and what should they read there's a lot of different things so there are some really good books um i used to recommend super intelligence uh and actually i would say that it's probably not that it's probably no longer the best first book to read and i would actually read something like um human compatible stuart russell's book which came out relatively recently and is a good solid introduction to the area the other thing is uh and i'm going to recommend a book that i haven't finished reading yet because it came out like the middle of last week i think which is the alignment problem by brian christian um so far it's very good um and that goes goes over again it seems like a good sort of uh introduction to the field for the general public to get a feel for what the different problems are if you're already um a bit more involved in sort of machine learning and ai stuff um i actually would recommend uh reading the alignment pod uh the alignment newsletter rather so i'm just gonna say this because i don't think robert's gonna actually plug this but i i desperately want him to so so rob's been doing a podcast version of the alignment newsletter which is just really great so just to toss that out there you can check that out as well but yeah so the newsletter is really really good um in that it's a weekly newsletter which summarizes um research that's happened in a week so i i think it's really good if you are already a researcher yeah um the the the problem that i often have when talking to um people who are actually know a lot about ai and a lot about machine learning is that they don't realize the extent to which this is like a real active field that people are publishing a lot of papers in that it's it's a growing field and um but it's still tiny right it's growing but it's tiny but that these are real problems that you can do computer science on and i think the newsletter is really good at giving you a feel for the kinds of uh papers that people are writing and the kinds of problems that people are making incremental progress on yeah and actually so uh people who've been listening to the podcast probably the episode i think before this one will be with rohin shah who actually puts out the alignment uh newsletter so these might be a good kind of back-to-back series to to watch or listen to um yeah well yeah rob thanks so much no i was just gonna say like i don't um it's a weird thing i actually don't feel weird about plugging the podcast because i take no credit for it i mean literally i just i i just read out the newsletter but if you if you i mean if you're listening to this podcast you're probably a person who likes to listen to podcasts um a person who likes to take in information through their ears and uh i like to think that i do a better job than text-to-speech software can there you go the technical terminology and stuff you know what and let's hope that's always the case uh i would do it anyway but there you go that's that's the spirit yeah very human um thanks so much rob really appreciate it i will be leaving links to all those books actually and of course your youtube channel uh in the blog post that will accompany this podcast so if anybody wants to check out uh rob's channel highly recommend it and i really appreciate your time on this one thanks so much for having me on the show
Up Next

10:16
Reinforcement Learning with Human Feedback (RLHF) Explained
@CodeEmporium
28.7K views•2023-12-11

73:14
3D Computer Vision: Lecture 1 Part 2 - Projective Geometry
@cvrplabatnus8618
15.3K views•2021-01-20

13:03
Bypassing Tor Censorship: Bridges and Pluggable Transport Guide
@Coding_ForEveryone
397 views•2024-06-11

18:41
Neural Networks Explained: Math, Layers, and Learning Fundamentals
@3blue1brown
21.9M views•2017-10-05
Related Study Plans & Knowledge Roadmaps
Structured learning paths in Artificial Intelligence
artificial-intelligence
PINNs: Fluid Dynamics with PyTorch & DeepXDE
01Calculus & Fluid Dynamics Foundations
02Deep Learning & PyTorch Basics
03Introduction to Physics-Informed Neural Networks (PINNs)
+ 3 more learning modules
32h6 modules
Explore Roadmap
artificial-intelligence
Aligning LLMs: DPO, TRL & Custom Datasets
01Foundations of Python & Machine Learning
02Transformers and Large Language Models (LLMs)
03Aligning LLMs: SFT and RLHF
+ 3 more learning modules
24h6 modules
Explore Roadmap
artificial-intelligence
Federated Learning: PyTorch, Flower & Privacy
01Python & Machine Learning Foundations
02Deep Learning Basics with PyTorch
03Introduction to Federated Learning
+ 2 more learning modules
35h5 modules
Explore Roadmap
artificial-intelligence
Securing LLMs: Guardrails AI & NeMo Gateway
01Introduction to LLMs, Python, and APIs
02Understanding LLM Vulnerabilities & Threats
03Defending LLMs with Guardrails AI
+ 2 more learning modules
15h5 modules
Explore Roadmap