







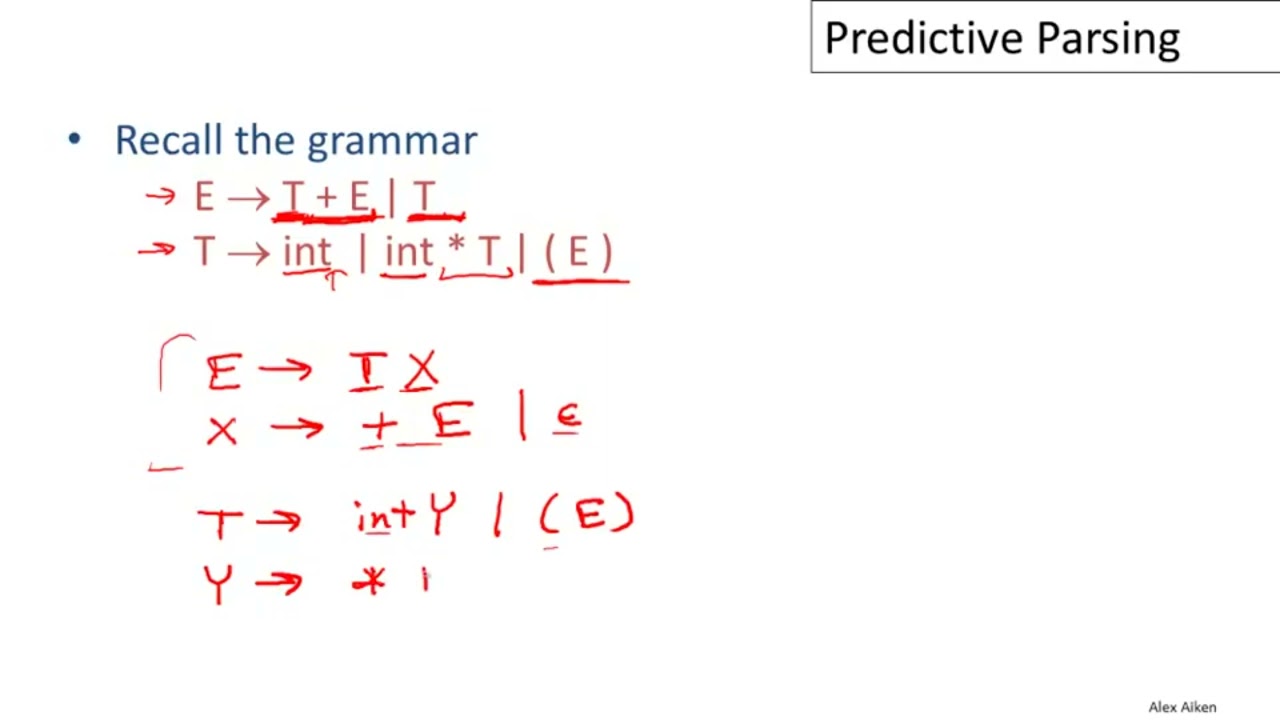






Parsing is the process of finding all possible parse trees for a given sentence according to a context-free grammar. Two fundamental strategies exist: top-down parsing starts from the start symbol and explores possible expansions, while bottom-up parsing starts from the input words and builds upward by combining adjacent substrings. Both approaches can explore many paths that don't lead to valid complete parse trees, making them inefficient. To achieve polynomial-time parsing, dynamic programming approaches like the CKY algorithm are used, which require converting the grammar to Chomsky Normal Form (where each production has either one terminal or two non-terminals on the right-hand side) and caching intermediate results to avoid redundant computations.
Syntax Parsing: Top-Down, Bottom-Up, and CKY Algorithm
Added:[Music] so welcome back for the second lecture of this week so we had started our discussions on syntax so yes in the last lecture he had talked about what is the formula for doing the syntax passing so we had talked about context-free grammars now we will see how do we use context-free grammars for the actual policy so so let us take a simple grammar in terms of a CFG following so you are in the Gamma it is said that sentence can be a noun phrase followed by a verb phrase or in or generally for being on place for by our fridge or using simple a single or fridge non trees can be a determiner followed by a nominal nominal can be a noun and so on so all the various possibilities are shown here and similarly these are all the pre terminals that are giving me terminals that are words my lexicon so this is one such grammar and now using this grammar I I can write various and and sighs okay so for example I want to write the sentence the men read this book okay so I want to write the sentence the man that this book now how do i what kind of rules the grammar do I use so that I can generate the sentence so I have to write the man read this book okay so let me just do it quickly on on the paper now the sentence can be a noun phrase for bigger fish or an absolutely followed by a number of ways or ever fits in this case it is no disturb this knocks Larry Nora verb so it has to be non faithful by office so have to first start by in on fridge for by you go fridge okay and I'll assume that the knob the man will come in on fish and read this book will come in well fridge so what would be the next elevation so many have to get dumb in so have to get something that says did I mean a nominal okay so so here I have to say did a minor nominal and go fridge okay and did a minor can can give me the and normal or can give me noun which can give me the word man okay so in some steps I can determine it to the nominal okay and if I want to complete this I'll say the man to now the work fish I have to derive read this book okay so a fridge goes to work and non fridge is there something like that yes well fridge goes to woven non fridge so I'll use this and save the men whoop non fridge wolf can directly give me read the men read non-fish and from non Fisher to drive this book slept again right this data miner for by nominal this will be coming to the miner the man read it a minor nominal and this will give me this this will give me known and this will give me okay and that will give me the horse and is the man that this book that's how I derive a sentence using this gram so now once I have this derivation I can use this derivation to denote what is the particular syntax tree that underlies the sentence as per this grammar okay so the same derivation can be used for to show the parse tree so this is my derivation and this derivation can be shown using this parse tree look at some sentence you drape NP VP from NP you drive determine a nominal VP verb a noun phrase non fasion to this particular subtree okay so this is exactly what was the derivation that you did for the sentence in my grammar so that can immediately tell me what is the problem of passing I am given the grammar and I am given the sentence in my language so given the sentence in my grammar I want to find out what is it sexual past tree and they may not be a unique passed away Academy multi L parse tree so the process of passing is to find out all the possible parse trees for a given sentence as for my grammar so so find out all trees whose root is the shot symbol s okay because I have to start with the start variable in my context-free grammar and which covered exactly the words in the input okay now what are the constraints on which act with the Parsee suppose my sentences book that flight so what are the constraint in my pass they should be three leaf nodes book that inflict and I am I should start at the start node and then I have to explore all the possible Lu says that I come up with a tree it's starting with s as the root node and book that flight as the only three no three leaf nodes okay so yes the tree must have one root start symbol s and that tells me that I can explore it in at least two different ways one is I can do it top down it starts from s try to find out all the possible possible trees I'm finding out I can have as for my grammar and see if there is one tree that can give me the only the leaf nodes book that does he stop down other opposes bottom up I start from book that flight go upwards what are the non-terminals and then see if any of this combination can lead to a full tree starting from us okay so these are two different strategies and that's what we will discuss how do we use it top-down or bottom-up approach for passing given this Trump so let's take this grammar okay so you have certain rules so left hand side is mainly the rules for non terminals and peeta pre-term loose and red inside are for the lexicon pre terminus deriving the terminals now using this grammar you want to find out the pass for book that flight and we will he is both the top-down and bottom-up strategies fun for finding out this mastery see this is also what is the expected path string book that flight this is a whole were fridge starting from a verb and in on fridge so book is a verb and and this that flight is a non-stretch okay so I want to come up with this path string given the grammar and how do I do that in a I know the domestic manner using the using my top-down strategy so how do I start so I have to start from my so start node root note in top down and using my grammar as mega my ever see what the different possible loose I can apply at this point keep on going downwards okay so I start by assuming that the input can be divided by s then find out the trees that you start with this looking at the rules that were having s on the left hand side because what are the all the different things that s can derive now when you are going downward in your tree once you opt in the part of speech category you will see if that matches the word in the leaf nodes if it is not matching you will go back and try out some other path and if there is an entry there the power to switch type categories are not matching the words at the leaf nodes you will check that okay so now so let us see so I am starting with this okay now what is my first rule so what are the different rules from s so first tool such as can go to and PvP so what I will do I will try to explore that path s can go to NP VP now from nth what is the next possible rule so next tool from NP and we can give me a pranaam okay and be give me a preneur again i will try to explore this further with pronoun give me the so pronoun will be the first word now pronounce AP terminal now what is the first be terminal book so pronoun can never give me a book book is not depend on so so this path is not correct so I'll go back from MV I will try to express some other part okay so NP can also give me proper no so you see these are the rules in sequence in your in my grammar NP can give me a pronoun and we can give me proper now so again proper known is a P terminal that cannot give me a book so again I cannot accept this part so I'll go back next to Liz and B gives you determiner followed by a normal okay so again the first word has to be determiner that in the sentence but the first word is book that is not a determiner okay so again this path has to be this part is not correct now we see in the grammar there is no other rule that has NP on the left-hand side okay so that means I have to now go back to the initial assumption that s will derive and be VP so I have to try out the next possibility as for my grammar the next possibilities s can give me auxiliary followed by non faithful by over fridge so let me do that so yes s is given me oxen the non present verb phrase again what is auxilary ox very easy Peterman and that gives only does it does not give me book okay so again this path is not correct and auxilary cannot give me anything else so I have to again go back and try out something else from us and the only remaining thing is VP says gives me everything okay now I will go to my grammar what are the rules from VP he can give me a verb that is the first thing maybe gives me about good now what also gives me book that question is there but what happens to the other two words my sentence that flight wolf gives me book but that flight is not covered in this tree so this is not a valid tree yes that flight there is no other no no node is starting from s that captures this this is again not a valid tree so I will try out something else with VP so next possibilities were followed by and B okay were followed by envy and verb gives me book well now from NP I have to get that flight now again some NP I can get pronoun pronoun cannot give me that yes then I can get proper known it will also not give me that then I think from n being it did a - all by now nominal okay and that is it a minor and from nominal I can go to known and this can give me light so that means by doing all this exploration is systematically I can come up with a pass tree that starts from s and exactly covers these leaf nodes book that Flint in my input so that is my top-down parsing strategy okay so that is clear so you are given all the rules you start from s and try to expose in some order you can take it you can try to explain the same order that is in which they are given to you okay you might try to put them in the order in which they are actually used in in language so which one is more probable than other that is also okay but again but but you see that this request a far too many steps right so you you are exploring paths that will probably never lead to the whole path tree so this this this means there is certain ways to have a space so we will try to take that problem that how we can avoid that this way this was my top down parsing know how what do I do in bottom-up parsing in topic I started with this in bottom-up I will start with my leaf nodes I'll start with book that flight and I will try to grow my tree upwards and see which one can give me if completely is starting from s so the passage starts with the words of the input and tries to be reach from the words up by applying rules from the grammar one editing and parcel looks for the places in the past in progress where the right-hand side of the rule my treat okay in top 10 we were looking at always a left-hand side if the current non-terminal is what is the rule in the left-hand side so that accordingly I will I am trying to generate the right-hand side here I am seeing what what in the right-hand side I already have accordingly I rule in my grammar so so let's do this bottom-up parsing so I have the sentence book that flight I start by seeking what are the notes my grammar that can that can generate this ok so I start by say book and the first tool that there is bookish known ok then I go up to now and say nominal gives me now fine and normal can gives me nominal file followed by you know so I'm going mighty up good but now I down that is a pre terminal and non will not give me that ok so that is not a no so this is an inconsistency except to go back and see ok what is the next possible rules from nominal so I have to drive from nominal nominal for by P P so remember again we are seeing in which rule this occurs in the right hand side okay and accordingly I will take the the production nominal gives me nominal for way people know can can PP give me that flight so from P P so from that I try to go grow it upwards I see did a minor did a minor comes in that inside of this rule and pig is minted a minor nominal and flight again I grow it upwards it gives me now and nominal can give me now okay so this looks a nicely but now can I attach PP to empty so yes if I grow and be upwards I'll say ok ask and give me n before by VP this creates a problem in that this work fish does not have any children so it cannot take me to any leaf node okay so this is not valid if I go to this part can P P a destiny not and did a minor and and B I think there is no rule in my grandma that people can be indeed a minor for by NP so I have to go back again try some other pathway ever business right-hand side VP yes s and determine the NAM and I'm non-fish what can they give to give me s again this does not work out so I try out something else with VP so I say VP gives me we be followed by a proportional face again proportional face does not give me determine if I have a non non which this will not work out again go one step down so earlier I was saying we be driving Bob no I am saying okay VB dress work for a B and B does that work yes if I can attach this VP do this for when this knowledge okay and then I can say that I can derive this VP and this gives me the whole parse tree so this is my bottom up strategy I start with the words in the leaf in in the Leafs try to grow them upwards by seeing what is the rule Mike my grammar where this occurs the right hand side similarly I see here and so on and finally can I build them as a single Utley starting from s and that strategy finally gives me this particular tree so if we just try to compare this top-down versus bottom-up approaches so what do we see so what we were seeing in top-down we were always seen variable this non-terminal appears in the left hand side and I immediately do the production so what happens that I can X I can always explore options that will never lead to the full path okay I can always find options that will only give me one word but so so all the options were giving me a pass is starting from us in in the top-down strategy but it might happen that some options are giving me if I'm capacity where all the words are not covered or some extra words are covered okay so this actual connection to the actual sentence is not taking care so in the bottom up it is the other way round so you are always seeing the words first so you are exploring that that those paths they are covering the whole sentence but it might happen that the path that you come up with is not a complete path because it is not having it routed yes okay so they may not be a full pass and they are averse to just passage in both top-down and bottom-up okay so you are seeing you were explaining not many paths that are probably not read a bit and this depends on branching of my grammar in either direction okay so to avoid this problem and obtain an algorithm that works in polynomial time so you will use some dynamic programming approach okay so we have been using any programming a lot in this course so we use that for agile distance then we use that forfeitable decoding kind of algorithm now we will see how to use that for obtaining an efficient parsing algorithm so so idea is that can we cache some intermediate rails instead of exploring all the different possibilities that are not relevant so by doing this caching I can obtain a polynomial time parsing algorithm for context-free grammars okay and there are different dining programming algorithms that are both top-down agile is bottom-up and they can work in roughly order of n cube time where n is the length of the sentence number of words in my input stream so what are the different approaches for dynamic programming passing so one very popular algorithm is CKY algorithm that works in bottom-up manner okay so you will do it for individual words then you're going to the sequence of two words and so on after you go to the whole sentence and so the only thing is that it requires some normalization of the grammar that we will also see what is the normalization then there is early parser that is you're getting very popular that works in top-down manner it does not require a normalization of the grammar and slightly more complex than the CKY algorithm and a generic framework is something called a chart for a spacer where for individual phases in the sentence they will see what are the possible peach they will retain in the chart and use that for for the higher level teacher okay so and they combine both both of these approaches bottom-up in and top-down so we will only focus on CKY algorithm that how do we use this for finding out paths in an efficient polynomial time so how does this CKY algorithm works now before that we have seen that this requires normalization of grammar so what is that so it applies hiki like algorithm so my grandma must be converted to a normal form called called Chomsky normal form okay and what is the constraint in Thompson of the form so the constraint is that all the production of my grammar should be having of should be having one of these two forms that is either exactly two Mon terminals on the right hand side or one terminal symbol on the right side so what do I mean by that in the context free grammars a rule is of the form a goes to gamma where is a non-terminal and gamma can be a sequence of terminals and non-terminals this is general CFG production so what happens in the case of Chomsky normal form the rules are constrained to be of these two forms a goes to B see all these are non terminals or a goes too small a small lazy terminal so left hand side is always the same it is only one non terminal in Thompson over phone what happens is that you put some questions on the right hand side so it can have a either only two non terminals or only one done so to apply CKY algorithm i must convert my grammar in any generic context-free grammar form to Chomsky no okay so what are the steps involved there's hardness test but we will see what are necessary for our keys so we will also see that how do we store all the possible phrases what are their passage in a triangular table in the CKY algorithm so let me quickly see let me go through how we convert the grammar to Chomsky normal form so the left hand side you have a grammar okay and I want to convert at the shop syllable so can you can please see go through the grammar ends and find out the rules that are not in Chomsky normal form so all these power one non-terminal giving me a one terminal yes in all these cases so they are pre terminal to terminal they are always in Chomsky normal form yes in one time were giving me a single terminal now let me go for upwards so PP gives me the pushing for by non non rich again one non dime not giving me to non terminus in CNF this is also in CNF this is also CNF but this rule is not in CNF VB goes to work one non-terminal giving me another non-terminal so how do I actually convert this to Thompson / form the idea would be I will find out what are the terminals that this derives so verb types book including prefer so instead of this rule I'll add a new rule were faced gives me book include and prefer okay and is this is a strategy similarly here this is in CNF this is in CNF what about this rule nominal goes to nom again I'll find out what are different things that nom derives book flight million money and I will add a rule nominal derives book flight million money this isn't CNF so here again and P goes to preneur I find out pronoun goes to I he she me so NB gives me I he she me as goes to vp is again not in CNF so he B gives me Bob and also verb man and D ok so I have to add these rules as goes to valve and P as goes to V P NP as goes to proportion and P okay plus 4v p going to verb I have to now take its next two we were going to book include prefer and the rule I will add is as goes to book included prefer as going to n be VP is fine but what do I do with this rule s goes to auxilary and p NV be okay so for this kind of rule s goes to auxilary NP v p where a single non-terminal derives three non terminals so what do i do I coin some new non terminal so I will say that auxilary a non face together make a new tour non terminal say x1 okay so what will in my grammar it will be X goes to X 1 followed by VP and X 1 will be auxilary for way and and this is equivalent to this rule and now this is in my Chomsky normal form so idea is that whenever you have a rule where you have to more than two non terminals you try to break them down such that it is one non terminal another non terminal this you can again further break down if needed ok and this is a simple a and if you have a rule like this it goes to B & B goes to C you take this - he goes to small C this is your terminal okay and also if B has something else it would take care of everything in this yes that's what we took we saw in this particular example so now if I convert this ocean of gamma dewdrops animals from this is how it will look like okay so you see that here s goes to V P now has multiple ooze as goes to over NP s goes to V P NP and as goes to book include prefer and so on for the other cases so in this lecture we had seen that how do we do a simple passing using top-down approach in bottom-up approach but they are not very efficient so can we do something better by using tandem programming parsing approach and for that we are trying we will be seeing CKY algorithm so how do you think of algorithm for an efficient passing what's equal with them requires normalization to some Chomsky normal form and we saw how do you convert the grammar to Chomp sing above so the next lecture that we will start with the Thompson normal form and see given a new given a string how do we parse it using secure algorithm
Up Next

CKY Algorithm Explained: Parsing with Chomsky Normal Form
@NatalieParde_NLP
14.2K views•2020-12-27

Computing FFT and Plotting Frequency Spectrum in Python with NumPy and Matplotlib
@1mviews876
120.4K views•2020-11-08
PCFGs: Inside-Outside Probabilities Explained | Lecture 25
@naturallanguageprocessing6035
14.2K views•2017-02-15

Enigma Machine Mechanics: WWII Encryption Explained
@JaredOwen
13.2M views•2021-12-11
Related Study Plans & Knowledge Roadmaps
Structured learning paths in Computer Science