












This video demonstrates how to train a robot dog (Bittle) to walk using reinforcement learning with NVIDIA Isaac Sim, showing that discrete delta PPO (a classification-based approach to continuous control problems) outperforms other algorithms like SAC and TD3 when combined with specific hyperparameters including 20 Hz action rate, 7-frame stacking, and movement smoothness punishment; the key insight is that treating continuous motor control as a classification problem with relative position deltas (rather than direct regression) makes the learning problem more tractable for reinforcement learning algorithms.
Reinforcement Learning for Quadruped Locomotion: Part 3
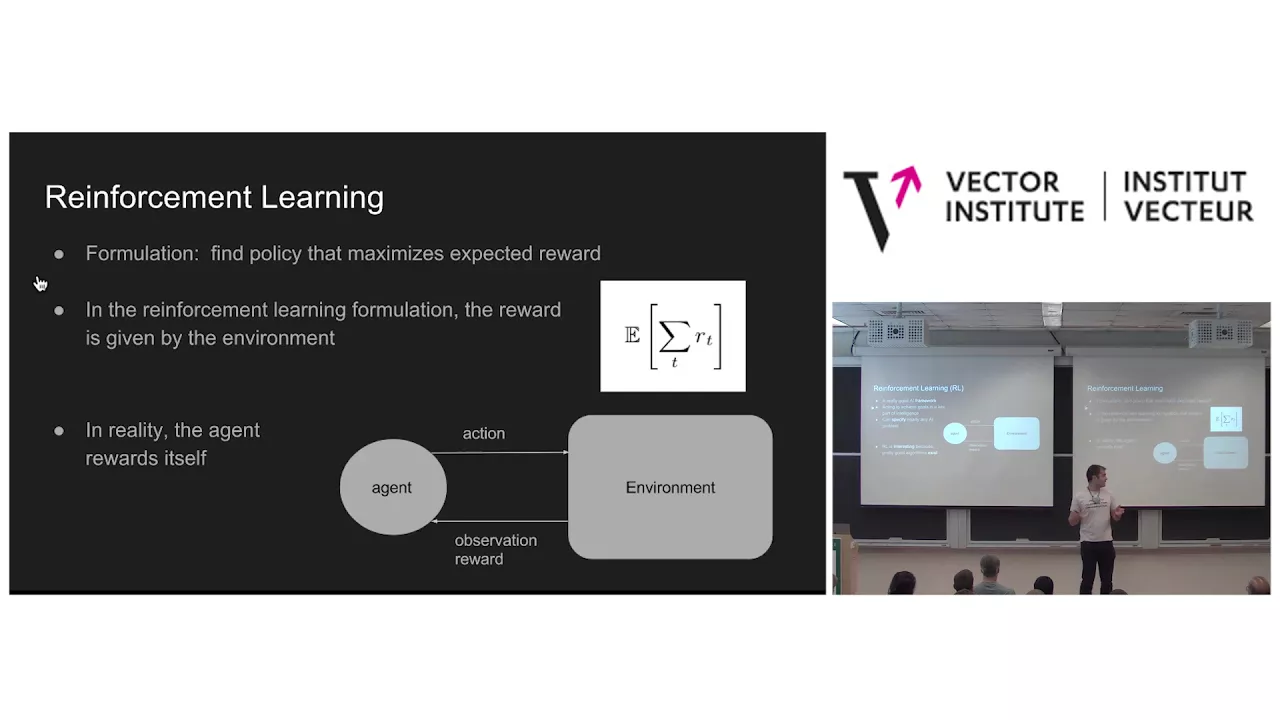
Added:Basic concepts of Reinforcement Learning (RL) including states, actions, policies, and the Markov Decision Process (MDP).
Foundational understanding of robotic kinematics and dynamics, specifically for legged or multi-jointed systems.
Familiarity with physics engines and simulation environments commonly used in AI, such as Isaac Gym, MuJoCo, or PyBullet.
An understanding of policy gradient methods and continuous control algorithms like PPO (Proximal Policy Optimization) or SAC (Soft Actor-Critic).
Sim-to-Real transfer techniques, such as Domain Randomization, to successfully deploy the trained policy onto physical robot hardware.
Hierarchical Reinforcement Learning (HRL) to combine low-level gait control with high-level navigation and path planning.
Handling hardware-specific constraints in real-time deployment, including sensor noise, actuator latency, and motor torque limits.
Advanced training methodologies for traversing complex terrains, climbing stairs, and recovering from dynamic external disturbances.
59.6K views1.3Klikes22:06Original Release: 2022-01-01
what is going on everybody and welcome to part three of the reinforcement learning with the biddle robot dog and nvidia's isaac sim a lot has happened since the last video each step a little baby step sometimes backwards but overall i'm getting much closer to my end goal and i'm learning a ton on the way the very first thing i did since part two was try adding a camera to the biddle my thinking here was that a camera would be capable of informing the biddle of at minimum the horizon but also later even more information such as objects that the biddle would need to navigate around and so on the real biddle also has a front camera option so this seemed like a really good next step so i learned how to attach the camera in the isaac sim and then all that was left was well how to access the camera and actually get the data but we have the camera next for anybody who is following along i don't believe i ever explained how to change the color the official way in the documentation just doesn't actually seem to work for me so the way that i've been doing it is under that looks section of the biddle uh dog in the sim you can change the material color manually there the main code to get the data from the camera is here and after running into a bunch of errors and using opencv instead of matplotlib to show it here's an example of the output so now that i've got the camera finally working the first thing i want to do is save a bunch of these frames so that i can use them to train an auto encoder on the imagery the idea here is once i have an auto encoder trained i can use the encoder part to encode the imagery from the camera down to something like four flat features for example if you're not familiar with auto encoders i did a video tutorial on them and i'll put a link to that in the description so now that i've got the data i whip up an auto encoder again i'm just going to zoom through this the auto encoder and the concept of an auto encoder is super basic the idea here is that we're just going to have some unconvolutional layers then flattened down to a fully connected chokepoint that is as small as i can get to start i literally just copy and pasted the code from the autoencoders tutorial on pythonprogramming.net after copying and pasting i just spent some time changing some of the variables hitting some errors fixing those errors and i was on my way trading the auto encoder once the auto encoder was trained i wanted to see both the fully encoded features of course and then also the result of decoding back to get an idea for any information loss that's going on and also just to see how small of a choke point can we get away with so here are some examples essentially there are three photos this is a 25 feature choke point for the image so the image is input into the auto encoder and then it's encoded down to in this case 25 values the first photo that you see is the original the second photo is a visualization of the 25 values just in a 5x5 grid format and the third photo on the bottom is decoded as the original it's just basically the original image decoded back so as you can see there's definitely some noise some information loss but that's perfectly fine all i think i need to capture in these features right now is the horizon and i think we've done that here's another example i then try to go from 25 features down to nine retraining the auto encoder and again i check some samples and that also seems fine and i even did a four feature and again that seems totally fine for my needs to be honest it might even be possible that this can be encoded into a single feature but right now i want to see does this work in the bot in the sim unfortunately it's at this point where i learn how much this camera sensor seems to slow everything down what you see here is me printing out the frame number per frame in the sim and this is real time it's very slow it's too slow it looks like about seven steps per second we can expect to do millions of steps per model test and a sufficiently trained model to be about 50 million steps just to guess at seven steps per second that puts us to 7.14 million seconds that's 119 000 minutes 1984 hours and 82 days that's a few days too many in my opinion if i ever get to training in real life that is probably something i'll be looking at in terms of time to train but the point of the sim is to speed up the r d the slow down here appears to all boil down to line 40 which is where we're actually grabbing the camera sensor's values i don't know any way around this this has to be done in the loop every step there's got to be a better way i'm sure there is i just don't know it in my hunt to speed up the camera i stumbled upon an imu sensor example here you can see me poking this little ant thing and the sensor values are updating in the imu sensor example window if you don't know imu stands for inertial measurement unit and it's used to measure forces on in axes so also the the real bitter robot has one it looked to me like the imu response right here was extremely fast and cherry on top there was sample code to go with it in my opinion the imu readings are probably even better than the auto encoded video at least for now there are other things that we can get from video that we can't get from an imu sensor but for now this is pretty good i'd call this lemonade out of lemons using the imu demo script i start to port over everything to my biddle attaching the imu itself adding in the code that will let us probe the imu data and then printing it out to see if it actually worked running everything looks like it indeed actually worked and if i move one of the legs we can see the imu data is indeed updating and we can see it's happening very fast around the time that i'm rnd the camera sensor a new version of isaac sim comes out with various major changes and i accidentally delete the entire project directory when uninstalling the older sim version so i wind up rewriting the whole agent and sim code not the worst thing ever though i kind of already wanted to rewrite it just to clean it up essentially anyways so cool after doing all of that i finally have my first working observations and actions environment along with those imu readings for the observations and we're ready to learn some stuff one of the other additions that i wanted to make was something to better punish for this like wiggling jitteriness various commenters brought up things like mimicking lactic acid and such i thought about measuring how wiggly a line was and embarked down a journey of measuring the smoothness of a line but eventually i went with just simply punishing for every direction change if you jitter a lot the punishment is very high and if you take strides the punishment is very low i then work to apply this but not only does this take a while i'm also simultaneously trying to get things like continuous ppo to work as well as soft after critic and even discrete delta ppo as one of the viewers suggested i try but every move i make takes a very long time to apply now and weaving each individual algorithm into my current environment is very messy it would help to convert my environment to a full-on gym inheriting environment and if i'm doing that i might as well start using stable bass lines 3 which will make iteration much faster stable baselines 3 is for reinforcement learning in python like sk learn is for general machine learning the idea is to make reinforcement learning very modular and easy to apply various reinforcement learning algorithms to your problem to make actual use of stable baselines 3 you need to convert your environment to an actual gym environment with at minimum an init step and reset method for something like the simulator here that closes very messy if you just break it you might also want to have a close method that cleanly closes the environment once you've converted your environment while stable baselines 3 does have a quick sort of check end method i find this doesn't really fully inform you if things are going to work right so i went ahead and just made a double check and to make sure things are stepping and resetting and cycling episodes as we hope and finally i get to the point where it works and now i'm ready to play with some new algorithms and stable baselines 3 in general one of the other early initial things i added in is frame stacking which is where rather than having a single observation per step we have a stack of historical observations and the current observation so there's a slight history of what's been going on after this i start training and comparing models across various algorithms like td 3 ppo and sac i also begin testing different hertz refresh rates essentially how many steps per second does the biddle do things i originally was doing 60 since that's the simulator's default but then i found 30 to be a bit better i also tinker a bit with forcefully smoothing moves various frame stack sizes obviously other hurts rates and much more and then this is also where i began poking into discrete delta ppo since so far this seems to be my best performer let's cover the concept of discrete delta with classifiers like native ppo robotics with motors and servos and such is generally seen as a continuous control type of problem it's not a question of classification like go left or go right you might have a higher level control algorithm that does something like that but when you're trying to control servos it's a question of what position do we want to set the motor to this is a continuous type problem and these are much more challenging to solve with gradient descent just in general if you can pick any number between negative 1 and positive 1 there are theoretically infinite choices of course with many electronic components they are mapped to values like 0 up to 32768 or something like that so this is theoretically actually discrete but these are way too many discrete values for an actual classifier and this is why they're considered continuous problems instead to understand why this isn't treated as a discrete problem even though it theoretically is discrete you would want to imagine having training data that shows based on some input you want to set the servo to let's say 10 000 but the algo picks 1001 well 1001 would be considered wrong and this is why we want to treat it more like a regression style problem rather than a classification problem but again this is very costly because treating something this way takes much longer to solve because of gradient descent and just the nature of having near infinite possibilities so the concept of discrete delta aims to solve this consider having three discrete deltas negative 0.1 0 and 0.1 think of these like relative values from the current position whichever of the three classifications of discrete values that the algorithm chooses is simply added to whatever your current position is so no longer are there infinite possibilities or even 32 000 possibilities there's really just three so imagine your current position is 0.62 and the algorithm picks 0.1 you add 0.1 to 0.62 and you get your new desired motor position of 0.72 if we're acting at 30 hertz for example this means we can go fully in both directions three whole times a second which for our little biddle is way more than enough but we might also want some more fine motor control than that that might even be too fast so something like seven bins might work and here are just some two examples of some bins or classifications that i have personally tried on this problem with these we have some fairly large acting possibilities we've got some medium and some fine motor control right so we have everything from very quick rapid movements to very subtle ones and instead of having nearly infinite or even 32 000 possibilities we have seven and this is much easier for an algorithm to actually learn as i get into some of the results i couldn't possibly show every single version and every single test that i ran it was easily in the hundreds but i can at least give some highlights so first some of the things that i tried i tried various hurts so 120 60 50 30 20 and 10.
i tried td3 sac ppo discrete delta and continuous i tried because i ended up mostly going with discrete delta ppo i tried various deltas as well as numbers of deltas so different delta numbers but then also like maybe only three or five or seven or nine and so on and then also various movement punishments more on that in a little bit and then also frame stacks so again the historical observations coming through for the current observation i tried 3 7 20 and 60 for example so now for what actually worked the best performing algorithm by far is discrete delta ppo uh it is possible though that you know because it's discrete delta it's going to learn faster than something like soft actor critic or td 3 for example so or continuous ppo so it's possible i just simply wasn't patient enough and more more research is going to be needed there uh the deltas that i went with uh were the following negative 0.3 negative 0.1 negative 0.03 and so on back to the positives again i tried many different deltas many different numbers of delta so as you can see here this was seven deltas that i ended up going with the hertz was 20. i found the lower hertz tended to to do better but 20 and 10 were pretty equal in performance and i felt like 20 actions per second was better than 10 most likely so that's what i went with and honestly i have no idea what what's the actual realistic hurts that i could achieve on the biddle uh like physically i don't i don't actually know next we had movement punishments uh the main punishment here being left to right movement right the what i'm trying to do is is develop a straight walking gait so any movement left to right is a direct punishment and then i did other various punishments like punishing for wiggles and punishing for just trying to get the gate to be more realistic so many people suggested before doing things like simulating like lactic acid and stuff like that and i did find that of all my crazy ideas the best idea that performed the best was quite literally just a punishment every time the servo direction changed so so the calculation for that is just like 5 is this 5a basically it's every single movement that was made divided by um the move punish div and then i just square this so the move punish div is 80 and then all movements is actually every servo direction change from the last 20 steps again this was just yet another hyper parameter that i tested but 20 steps is one second at 20 hertz so every single direction change of a servo is a punishment for the last second essentially and again i tried all kinds of different ideas but this seems to be the one that worked out best so getting into some of the results now this is a seven frame stack discrete delta ppo or ddpo example no movement punishment and it's a good example of what can happen if you don't punish jittery movement along with an example of how these reinforcement learning algorithms can find themselves in a sort of local optimum for rewards that it's going to be nearly impossible for that model to ever break away from ever again into the future it also looks like it could be a slight abuse of physics in this case now here is a more appropriate gate and walker this is a seven stack ddppo with jitter punishment and this is about 10 million steps into training and just to be clear the console that you see there the leftmost number is the total reward and then the other number is that the reward for that very specific step so this isn't the straightest of walkers but there is a clear gate here it's the first of the models to really give me any hope that this this could ever uh work and also check out this move about two million more steps into training that same model it's beginning to look pretty good but the upper legs don't really seem to want to move very much but honestly models like this are super rare to get most of the time what i'm seeing is more like a true winners like this and he's not done yet there we go as cool as a model that does that uh to travel might be i'm really after a regular walking gate and then there's models like this guy all i can say here is that reinforcement learning algorithms have no vanity they do not care how silly they look and you might be wondering how this model ever learned to do this over something else and my suspicion is this is probably to blame i don't know what's going on there but again abuse of physics so this is the model where i finally begin to settle on most parameters i'm all in on discrete delta ppo uh and those parameters i settled on are the ones that i showed earlier like 20 hertz 80 punish div seven frame stack uh the deltas that i showed earlier and so on i like this one a lot it looks like a realistic gate uh there's obviously tons of room for improvement but this shows a lot of promise and this is about five million steps into training unfortunately this model evolves into this model about 11 11 million steps in while the average reward here is better i'm not really a big fan it clearly wants to keep a very low center of gravity and you can also see it's doing this sort of like move stop move stop move stop and it's subtle here but about 20 million steps in here's our guy it's not ideal it's a very reliable and stable gate but i'm just not a fan yeah you can even see that when this model does trip itself up it is capable of recovering and continuing on its way which again is is cool but i'm just not the biggest fan of this gate for the final biddle model for this video i went ahead and added a punishment for the z axes bounce that's been going on and this is done in the form of a standard deviation specifically i'm just simply calculating numpy standard deviation of the z history uh the reward is then just a minus equals of the standard deviation and then i'm dividing again by a standard deviation division similar to the other divisions that i've done like with movements and stuff so the standard deviation is applied to a history of 10.
i actually have not tinkered much with making that 20 or you know any other number so 10 is just the one that i went with i i basically just ran it in the simulator looked at some of the outputs and tweaked that until it was a number that i felt like yeah that's how much i want to punish it so probably more r d could be could be done there and honestly this one reminds me of some of the earlier models before they became hoppers it's definitely more of a walker fairly stable good reliable rewards i think the biggest thing that i notice now is that body roll i am tempted to also punish for the role as well we can access that with the imu but i'm i'm just kind of weary about how much restriction and i do kind of wonder if we just let these models go for a few more tens of millions of steps if things would just smooth out on their own because it's more efficient this model is 20 million steps in so far and the hoppy model i let continued training and is currently 65 million steps in still hopping around so i think to some extent a natural gait would be naturally found but it's also true that gates in real life are indeed determined by limiting factors like minimizing energy costs and joint wear and tear and then also just body stability is definitely a thing it makes sense so that the animal's head and brain isn't just bouncing around and so vision is stable so it's tough for me to come up with final decisions about a good balance for for rewards and restrictions and stuff and every time you introduce some new punishment you run the risk of adverse impacts that you just did not foresee or intend so anyways definitely still much more trial and error to get through i'm definitely still learning a ton of new information and new things i also appreciate all the comments lots of great suggestions and also just discreet delta ppo is something that came from a comment i don't think i would have stumbled on that on my own so yeah thanks to everyone for your input so that's all for now if you'd like to learn more about neural networks and how they work there's a book maybe you've heard of called neural networks from scratch by myself and daniel kukewa you can learn more about that at nnfs.io otherwise i will see you all in another video you
Up Next

5:11
Building a Quadruped Robot: Servo-Driven Crawl Gait Prototype
@JonathanLi-9813
437 views•2026-05-07

14:50
Autonomous Sailboat Heel Control: N4N1 Field Tests
@meholden
456 views•2025-03-14

11:04
How to Build a Self-Balancing Robot: Arduino Nano & MPU6050
@easytechzones
16.8K views•2022-03-09

25:22
Micromouse: The Fastest Maze-Solving Robots on Earth
@veritasium
23.5M views•2023-05-24
Related Study Plans & Knowledge Roadmaps
Structured learning paths in Robotics
robotics
Robotic Sailboats: Arduino, Sensors & Tacking
01Sailing Physics and Aerodynamics
02Arduino Programming and Electronics Basics
03Sensors and Actuators Integration
+ 2 more learning modules
35h5 modules
Explore Roadmap
robotics
Building Delta Robots: Kinematics & Pico
01Foundations of Delta Robots & Mechanical Design
02Electronics and Microcontroller Setup with Pi Pico
03Delta Robot Kinematics and Coordinate Math
+ 3 more learning modules
65h6 modules
Explore Roadmap
robotics
Building Ballbots: Dynamics, Kalman & LQR
01Embedded Electronics & Omniwheel Actuation
02Ballbot Kinematics & Rigid Body Dynamics
03IMU Sensors & Kalman Filter State Estimation
+ 2 more learning modules
42h5 modules
Explore Roadmap
robotics
Micromouse: Hardware, PID Control & Flood-Fill
01Electronics & Teensy Microcontroller Basics
02Sensors and Actuators: Motors, Encoders & IR
03Precision Movement: Implementing PID Control
+ 2 more learning modules
35h5 modules
Explore Roadmap