



















This StatQuest video teaches how to implement neural networks in PyTorch by creating a custom neural network class with weights and biases, performing forward passes to make predictions, and optimizing parameters using stochastic gradient descent with backpropagation to fit the model to training data.
Introduction to PyTorch: Build & Train a Neural Network from Scratch
Added:Fundamental Python programming, especially Object-Oriented Programming (OOP) concepts like classes and inheritance, which are used to define PyTorch models.
Basic linear algebra, specifically understanding matrix multiplication, vectors, and tensor representations of data.
Introductory calculus concepts, particularly derivatives and the chain rule, which underpin the backpropagation algorithm.
Core machine learning principles, including supervised learning, loss functions, and the concept of gradient descent.
Implementing specialized neural network architectures, such as Convolutional Neural Networks (CNNs) for computer vision or Recurrent Neural Networks (RNNs) for sequential data.
Mastering PyTorch's Dataset and DataLoader APIs to handle, preprocess, and batch custom real-world datasets efficiently.
Applying regularization techniques, such as Dropout, Batch Normalization, and weight decay, to prevent model overfitting.
Learning model evaluation strategies and deployment pipelines using TorchScript, ONNX, or framework extensions like PyTorch Lightning.
205.2K views5.5Klikes23:22Original Release: 2022-04-25
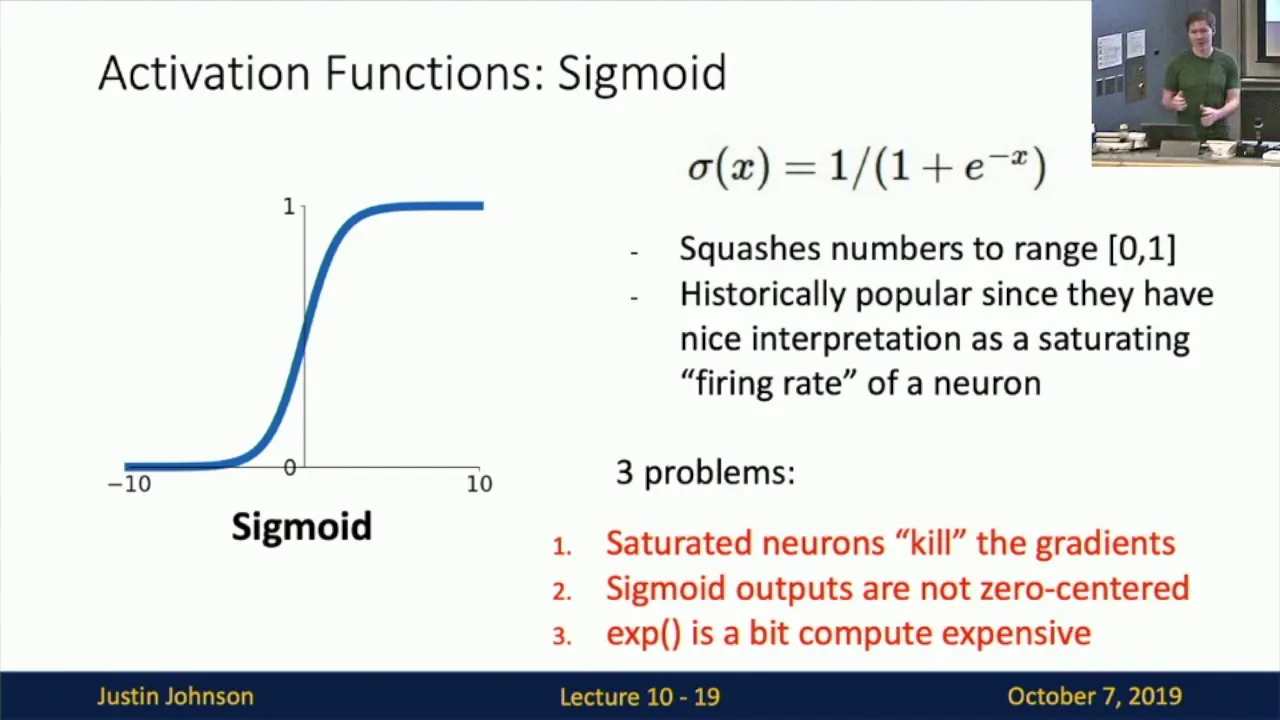
the statquest introduction to pi torch is here statquest hello i'm josh starmer and welcome to statquest today we're going to talk about the stat quest introduction to pi torch this stat quest is sponsored by lightning and grid.ai lightning and grid are awesome you can do cool stuff in the cloud hooray note this stat quest assumes that you already understand the main ideas behind neural networks the main ideas behind how neural networks are fit to data with back propagation the main ideas behind the relu activation function and how tensors are used in neural networks if not check out the quests lastly you can download all of the code in this stat quest for free the details are in the pinned comment below in neural networks part 3 the rel u activation function in action we started with a simple data set that showed whether or not different drug doses were effective against a virus the low and high doses were not effective but the medium dose was effective then we talked about how this neural network used weights and biases to slice flip and stretch the relu activation functions into new and exciting shapes to fit this pointy thing to the data set bam hey look it's statsquatch hey josh this neural network is awesome can we code it in pi torch yes however before we start coding let's label the weights and the biases now we need to make sure we have the necessary python modules installed in this tutorial we will be using pi torch to create the neural network and matplotlib and seaborn to draw awesome graphs if you need help installing any of these check the pinned comment below now that we have installed everything that we'll need to implement this neural network let's get coding the first thing we do is import the python modules that we will use first we'll import pi torch which is actually called torch because that is what it was originally called before it was ported to python we'll use torch to create tensors to store all of the numerical values including the raw data and the values for each weight and bias then we will import torch.nn which we will use to make the weight and bias tensors part of the neural network then we import torch.nn.functional which gives us the activation functions then we import sgd which is short for stochastic gradient descent to fit the neural network to the data the next two things we import matplotlib and seaborn are all just to draw nice looking graphs note the seaborn package is traditionally imported as sns which stands for samuel norman seabourn a fictional character in the drama the west wing the dude that wrote seabourn is just a big fan of the west wing and names his stuff after it strange but true bam now let's build this neural network with pi torch creating a new neural network means creating a new class so we start by creating a new class that in this example we call basic nnn and basic nnn will inherit from a pi torch class called module now we create an initialization method for the new class and the first thing we do is call the initialization method for the parent class nnn.module then we initialize the weights and biases in our neural network we'll start with weight w sub 0 0 which is set to 1.70 so we create a new variable called w00 and make it a neural network parameter making this weight a parameter for the neural network gives us the option to optimize it now since weight w sub 0 0 is 1.70 we initialize the new parameter with a tensor set to 1.7 note since this is a tensor the neural network can take advantage of the accelerated arithmetic and automatic differentiation that it provides lastly because we don't need to optimize this weight we'll set requires underscore grad which is short for requires gradient to false likewise we create new variables for the bias b sub 0 0 and the weight w sub 0 1 and then we create variables for the remaining weights and biases bam we have created neural network parameters for each weight and bias now we need to connect them to the input the activation functions and ultimately to the output in other words we need a way to make a forward pass through the neural network that uses the weights and biases that we just initialized so we do that by creating a second method inside basic nnn called forward so we can see what's going on let's move the code for forward to the top of the screen now the first thing we want to do is connect the input to the activation function on top so we create a new variable input to top rail u that is equal to the input times the weight w sub 0 0 plus the bias b sub 0 0.
then we pass input to top rail u to the rail u activation function with f dot rail u remember earlier we imported torch.nn.functional as f so that is where the relu function comes from then we save the output of the rail u in top rail u output now we scale top rail u output by the weight w sub 0 1 and save the result in scaled top rail u output we connect the input to the bottom rail u and scale the activation function's output then we add the top and bottom scaled values to the final bias and use the sum as the input to the final rail u to get the output value lastly the forward function returns the output thus given an input value the forward function does a forward pass through the neural network to calculate and return the output value bam now if we look at the entire class that we created basic nnn we see two methods init and forward init creates and initializes the weights and biases and forward does a forward pass through the neural network by taking an input value and calculating the output value with the weights biases and activation functions wow this is a lot of code how do we know it works and doesn't have any bugs good question squatch we can verify that the code works by plugging in a bunch of values between 0 and 1 that represent different doses and see if the output from forward results in this bent shape that fits the training data so the first thing we need to do is create a sequence of input doses and we do that with this command here we use the pi torch function linspace to create a tensor with a sequence of 11 values between and including 0 and 1 and we store the tensor in a variable called input doses note we can print out and admire the input doses by just typing the variable name input doses now the idea is to run these input values through our neural network so we'll make a neural network that we'll call model from the class we just created basic nnn note we are naming the actual neural network model because that is the standard variable name used when coding with pi torch thus from here on out i'm going to use the term model and neural network interchangeably if this freaks you out check out the statquest on models anyway now we can pass the input doses to the model which by default calls the forward method that we wrote earlier and we save the output from the neural network in a variable we cleverly named output values and now that we have both the input values to the neural network and the output values we can use them to draw this graph that has different drug doses on the x-axis and their predicted effectiveness on the y-axis first we set the seabourn style to white grid so the graph looks cool and then we use line plot to draw a graph of the data on the x-axis we put the original input doses and on the y-axis we put the corresponding output values and then we make the line green and wide enough to easily see lastly we set the y and x-axis labels and that code gives us this graph the graph tells us that the neural network we created earlier basic nnn does exactly what we expected in other words earlier we showed that when we put input values between 0 and 1 into this neural network the output was this bent shape which is the same as the graph we drew with our code double bam now that we can create a neural network in pi torch and graph what it can do can we pretend that we don't already know the optimal value for b sub final is negative 16 sure thanks squatch we'll just set b sub final to zero and we can now use pi torch to optimize b subfinal with back propagation the first thing we'll do is make a copy of the original class we created basic nnn and change the name of the copy from basic nnn to basic nn underscore train because we want to train this neural network then we change the initial value for final bias to 0.0 and we set requires underscore grad which remember is short for requires gradient to true setting requires grad to true is what tells pi torch that this parameter should be optimized we can verify that setting b subfinal to zero results in a neural network that no longer fits the training data by drawing a graph of the neural network's output like we did before only this time we create the model from basic nnn underscore train instead of basic n n and because final underscore bias now has a gradient we call detach on the output values to create a new tensor that only has the values in other words because seaborn doesn't know what to do with the gradient we strip it off with detach the original graph we drew for basic nnn shows effectiveness equals 1 when the dose equals 0.5 which is correct in contrast the graph for basic nn underscore train shows effectiveness equals 17 when dose equals 0.5 which is way too high and that means we need to train the neural network to optimize b sub final which means we need to create this training data all we have to do to create training data is create one tensor called inputs with the three input doses 0 0.5 and 1.
and another tensor called labels that has the observed output values 0 1 and 0.
now we are ready to optimize the last bias b sub final unfortunately this next step requires a lot of code but don't worry we'll go through it one step at a time also spoiler alert later in this series on how to implement neural networks we'll see how pi torch lightning makes this code a lot simpler anyway the first thing we do is create an optimizer object that will use stochastic gradient descent sgd to optimize b sub final remember we imported the sgd class from the torch.optin package way back at the start so in order to optimize b sub final we pass model.parameters to sgd which will optimize every parameter that we set requires grad equal to true we also set the learning rate to 0.1 in a bid we're going to use our new optimizer to optimize final bias but first just so we can see how gradient descent improves the value for final bias will print the current value the stir function converts the tensor value into a string so we can print it with other text and now we are ready to code the for loop that does gradient descent note if you're not already familiar with gradient descent and stochastic gradient descent check out the quests oh no it's the dreaded terminology alert each time our optimization code sees all of the training data is called an epoch so in this example every time we run all three points from our training data through the model we call that an epoch thus we start our optimization code with a for loop that counts the number of epochs and we set it so that we will run all three data points from the training data through the model up to 100 times now we create and initialize a variable called total loss that will store the loss which is a measure of how well the model fits the data for example if our unoptimized model fit the training data really poorly like this and we had this really large residual the difference between what the model predicts and what we know is true then the loss would be relatively large in contrast if the model fit the training data a little better and we had a smaller residual then the loss would be relatively small thus for each epoch we will use total loss to keep track of how well the model fits the data now we start a nested for loop that runs each data point from the training data through the model and calculates the total loss in this case that means the for loop starts with the first point in the training data and determines its input or dose and its known label or effectiveness then it runs that dose through the model to get a predicted output and then we calculate the loss between the predicted value and the known label with a loss function in this case we are calculating the squared residual where the residual is the difference between the output and the known value that said you can code any loss function that you want to use like the absolute value loss or you can choose from among the many loss functions like mse loss or cross entropy loss that come with pi torch anyways in this example the predicted and known value for the first point is zero so the squared residual is zero minus zero squared which equals zero now we use loss dot backward to calculate the derivative of the loss function with respect to the parameter or parameters we want to optimize in this example that means calculating the derivative of the squared residual with respect to b sub final and plugging in the predicted and known values note if any of this part is freaking you out check out the stack quest on back propagation lastly we add the squared residual to total loss so we can keep track of how well the model fits all of the data now we go back to the start of the nested for loop and select the input and label for the second point in the training data set and then we run the second point through the model to get a predicted output and then we calculate the loss the squared residual between the predicted and observed values next we use loss.backward to calculate the derivative of the loss function with respect to b sub final and and this is really important loss dot backward adds that to the previous derivative in other words loss dot backward remembers the derivative that we calculated for the first point and adds the new derivative that we calculated for the second point thus lost dot backwards accumulates the derivatives each time we go through the nested loop to be honest the first time i saw this it blew my mind this is because every time we go through the nested loop we create a brand new loss variable here and i couldn't figure out how the new loss could add to what the last one computed however it turns out that we create loss from the output value which in turn comes from the model and the model keeps track of the derivatives anyway the main point is that loss.backward accumulates the derivatives each time we go through the nested loop and we need to keep this in mind in contrast total loss does not automatically accumulate so we add the new squared residual to total loss then we go through the loop one last time for the last point in the training data set and that means we calculate the squared residual for the last point and when we call loss.backward we add the derivative for the last point to the other two derivatives and lastly we add the squared residual to total loss bam we made it through the nested loop and now that we're done with the nested loop we check to see if total loss is really small if so that means the model fits the training data really well and we can stop training so if total loss is really small we print out the number of epochs we've gone through so far and break out of the optimization loop to stop training otherwise if total loss is not small then we take a small step towards a better value for b sub final using optimizer.step note just like loss has access to the derivatives in the model when we call loss.backward optimizer.step also has access to the derivative stored in model and can use them to step in the correct direction now we need to zero out the derivatives that we're storing in model and we do that with optimizer.0grad note if we don't zero out the derivatives then the next time we enter this nested loop and call loss dot backward we'll add the new derivatives to the old derivatives from the previous step and that would be bad lastly we print out the current epoch and the current value for final bias so we can see how final bias changes each time through the loop now we've made it through the entire optimization loop and we just repeat it until total loss is small or we go through 100 epochs anyway now that we have gone through the optimization loop we print out the final value for the final bias bam now when we run this block of code we see the value for final bias before we optimize 0 and that value as we saw before gives us this graph of the output then we see the values that final bias takes on during each step of gradient descent and after 34 steps the total loss is tiny and the optimal value for final bias is negative 16.0019 which is pretty close to negative 16 the optimal value we used originally hey can we draw one last graph to verify that the optimized model fits the training data sure thing squatch we can verify that the optimized model fits the training data by graphing it with this code which is the same as what we used before except now we don't create a new model instead we just use the one we optimized and this is what we get which shows that the neural network does exactly what we expect triple bam now it's time for some shameless self-promotion if you want to review statistics and machine learning offline check out the stack quest study guides at statquest.org there's something for everyone hooray we've made it to the end of another exciting stat quest if you like this stat quest and want to see more please subscribe and if you want to support statquest consider contributing to my patreon campaign becoming a channel member buying one or two of my original songs or a t-shirt or a hoodie or just donate the links are in the description below alright until next time quest on
Up Next
16:44
Solving 1D Poisson Equation with Physics-Informed Neural Networks
@elastropy
26.9K views•2024-08-08

11:23
Solving the Heat Equation with DeepXDE and PINNs
@Dr.Mohammad_Samara
8.5K views•2023-07-17
23:54
Gradient Descent Step-by-Step: Machine Learning Optimization Explained
@statquest
1.7M views•2019-02-05
19:25
Enigma Machine Mechanics: WWII Encryption Explained
@JaredOwen
13.2M views•2021-12-11
Related Study Plans & Knowledge Roadmaps
Structured learning paths in Computer Science
computer-science
Building a Rust Debugger: ptrace, ELF & DWARF
01Systems Programming Foundations & Rust
02Process Control and the Linux Ptrace API
03ELF Layout: Inside Linux Executables
+ 3 more learning modules
38h6 modules
Explore Roadmap
computer-science
Container Runtimes: Namespaces, Cgroups & Go
01Linux Systems & Go Programming Foundations
02The Core of Isolation: Chroot and Filesystems
03Linux Namespaces: Process Isolation
+ 3 more learning modules
32h6 modules
Explore Roadmap
computer-science
Building a CHIP-8 Emulator: Rust & CPU Basics
01Computer Architecture Foundations (Bits & Bytes)
02Rust Programming for Systems Development
03CHIP-8 Virtual Hardware Specifications
+ 2 more learning modules
32h5 modules
Explore Roadmap
computer-science
Building BitTorrent: Go, P2P & Concurrency
01Go Fundamentals & Concurrency
02Networking Foundations & P2P Architecture
03Bencode Parsing & Torrent Metadata
+ 3 more learning modules
26h6 modules
Explore Roadmap