
















This tutorial demonstrates how to deploy Ollama, a powerful tool for running large language models locally, on a Kubernetes cluster. The process involves creating a namespace for resource isolation, deploying a two-container setup (main Ollama container for the LLM service and a helper container for automatic model loading), and exposing the service through a load balancer. The deployment takes approximately 4-5 minutes due to the large model file size (4-5 GB), and once deployed, users can generate responses by querying the Ollama API through the load balancer IP address.
Deploying Ollama on Kubernetes: A Step-by-Step AI Model Serving Guide
Added:Fundamental concepts of Kubernetes, including pods, deployments, services, namespaces, and YAML configuration files.
Basic understanding of containerization and Docker, as Ollama runs containerized within the Kubernetes cluster.
An introduction to Large Language Models (LLMs) and how Ollama acts as a tool to run and manage these models locally or in cloud environments.
Concepts of GPU hardware acceleration and how Kubernetes interfaces with GPUs using specialized device plugins (like the NVIDIA Device Plugin).
Implementing Horizontal Pod Autoscaling (HPA) with KEDA (Kubernetes Event-driven Autoscaling) to dynamically scale model servers based on GPU usage or concurrent requests.
Configuring Persistent Volumes (PV) and Persistent Volume Claims (PVC) to cache large LLM weights, preventing the need to re-download models on pod restarts.
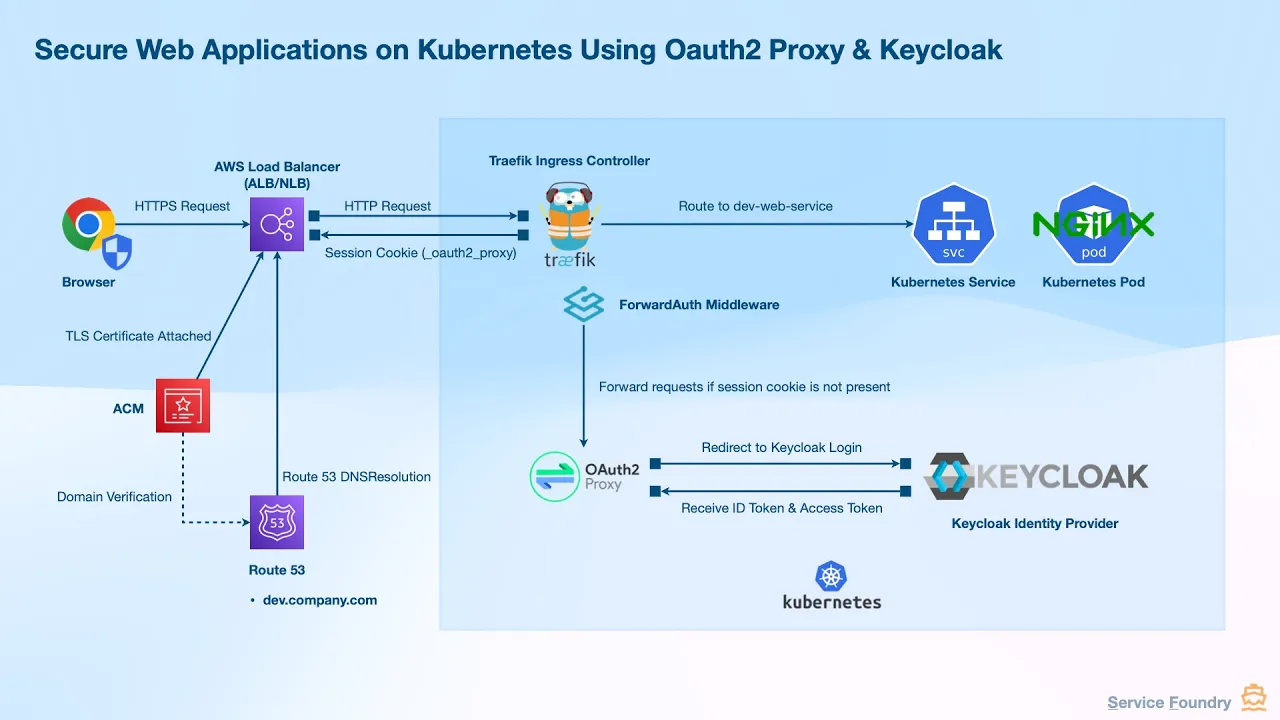
Securing the Ollama API endpoints using Kubernetes Ingress controllers, TLS encryption, and authentication mechanisms (such as OAuth2 or API keys).
Transitioning to production-grade LLM serving frameworks like vLLM, Triton Inference Server, or TGI (Text Generation Inference) for high-throughput and distributed tensor parallel serving.
1.2K views8likes6:42Original Release: 2025-11-23
[music] Everyone, welcome back to the channel Cloudex Club. In today's video, we are going to deploy Olama LLM on a Kubernetes cluster. We will see the procedure step by step. So if you have ever wish to run the LLM models like Olama directly inside your Kubernetes cluster, this tutorial is specifically for you. So we are going to set up the name space. [music] Uh we'll create a deployment service and going to load the Olama model and finally going to generate a responses using the Olama API. So let's go ahead and deep dive into the system.
and uh name space for pulama which will help uh keeping the resources isolated and uh easier [music] to manage. So let's create a folder mdir.
We'll name it asama.
I'll move into the folder.
Okay. Now here I'm going to create a YAML file for creating a name space.
So I have already saved the file. Now I'm going to uh apply that using the cubectl command.
Okay. So the name spaceama is created.
Let me see if I can see that into the name spaces.
So here it is.
This configuration runs uh within two containers. So there are two containers like main Olama container which runs the llm service and there is also a helper container which automatically loads the l uh Olama model using the port start hook.
So let me go ahead and create that vi deploy doty yamo.
Now I'm going to apply this file pl apply - app deploy dot yamlu.
Okay. So the deployment got created.
Now I'm going to check the deployment.
cubectl get ports name spaceama.
Okay, so it's getting created.
We'll wait for a few minutes. [music] Um I think it will take some time because it's a four or 5 GB file. uh you can run the watch command uh as well uh to monitor it.
So here I'll go ahead and uh pause the recording and we'll come back once it's deployed.
Okay, now you can see both pods got deployed successfully. It's uh taking around 4 minutes 35 seconds.
So when the pod is running the helper container will automatically loads the Olama 3.2 model. To access the Olama externally we will create a service called load balancer.
So I'll name this uh vi svcy.
I'm going to apply this file.
So the service uh /ola got created.
Now I'm going to check the serviceama.
So, Olama is running with cluster IP is this one and the external IP is this one and dison port this one. Okay, I'm going to generate a quick query from here. Let me put it here. So, I'm asking what is Kubernetes here and I'm going to query on the load balancer IP.
Hit enter.
waiting for the response.
So here you can see it has generated the response.
So thanks for watching. Uh if this helped you, don't forget to hit like, share and subscribe for more Kubernetes and AI content. Uh drop your doubts into the comment section. I reply to everyone. See you in the next video.
>> [music]
Up Next
18:27
Wildstyle Graffiti Construction with Bars: A Step-by-Step Tutorial
@MrGraffitiTutorial
54.7K views•2015-01-27

26:22
Walking in the City: Urban Rituals and the Flâneur in Contemporary India
@PSBTIndia
1.9K views•2016-08-02

9:49
FastAPI vs Flask vs Django: Choosing the Right Python Web Framework
@TechWithTim
302.5K views•2024-05-26

1:42
Game of Thrones Opening Credits: A Cinematic Analysis
@gameofthrones
46.3M views•2011-04-18
Related Study Plans & Knowledge Roadmaps
Structured learning paths in General & Interdisciplinary Studies
general-studies
Artificial Light: History, Tech & Human Impact
01The Pre-Electric Era: Fire, Oil, and Gas Lighting
02The Incandescent Revolution and Grid Electrification
03Gas Discharge and Fluorescent Illumination
+ 3 more learning modules
14h6 modules
Explore Roadmap
general-studies
Elevator Engineering: History, Physics & Cities
01From Hoists to Safety Brakes: The Dawn of Vertical Lift
02Hydraulic vs. Traction: The Engineering Physics of Elevators
03Modern Speed, Safety, and Algorithms
+ 2 more learning modules
12h5 modules
Explore Roadmap
general-studies
Rubber: Material Science, History & Geopolitics
01Origins of Natural Rubber & Mesoamerican History
02The Chemistry of Natural Rubber & Vulcanization
03The Geopolitics of the Rubber Boom & Colonization
+ 2 more learning modules
12h5 modules
Explore Roadmap
general-studies
Containerization: Evolution, Logistics & Trade
01Ancient Trade & Bulk Cargo: Amphorae to Barrels
02The Industrial Revolution & Cardboard Packaging
03The Containerization Revolution: Malcom McLean
+ 2 more learning modules
12h5 modules
Explore Roadmap